Sooner or later every AEM project needs to find content rather than navigate to it: every page on a given template, every asset missing a title, everything modified this week, every page still referencing an image you're about to delete. The tool you'll meet most often for this is the Query Builder, a predicate-based API where a query is just key/value pairs like path=/content/site and type=cq:Page. It's friendly from Java, HTTP, and a browser console, which is exactly why it's so often misused.
This reference covers what the Query Builder does under the hood (it compiles to XPath, which Oak runs against an index), the /bin/querybuilder.json endpoint and why it must never reach the internet, every documented root parameter and predicate, the Java API and its ResourceResolver gotcha, custom predicate evaluators, performance tuning with p.guessTotal and Explain Query, and copy-paste recipes. Where AEM as a Cloud Service and AEM 6.5 differ, the post says so.
It goes deeper on one topic from the JCR & Oak repository guide, which covers indexes, JCR-SQL2, and XPath. Read that first if Oak indexing is new to you. It also connects to the Dispatcher guide (blocking the endpoint), the Performance & Troubleshooting guide (slow-query hunting), and the Backend Development guide (services and resolvers).
What the Query Builder actually is
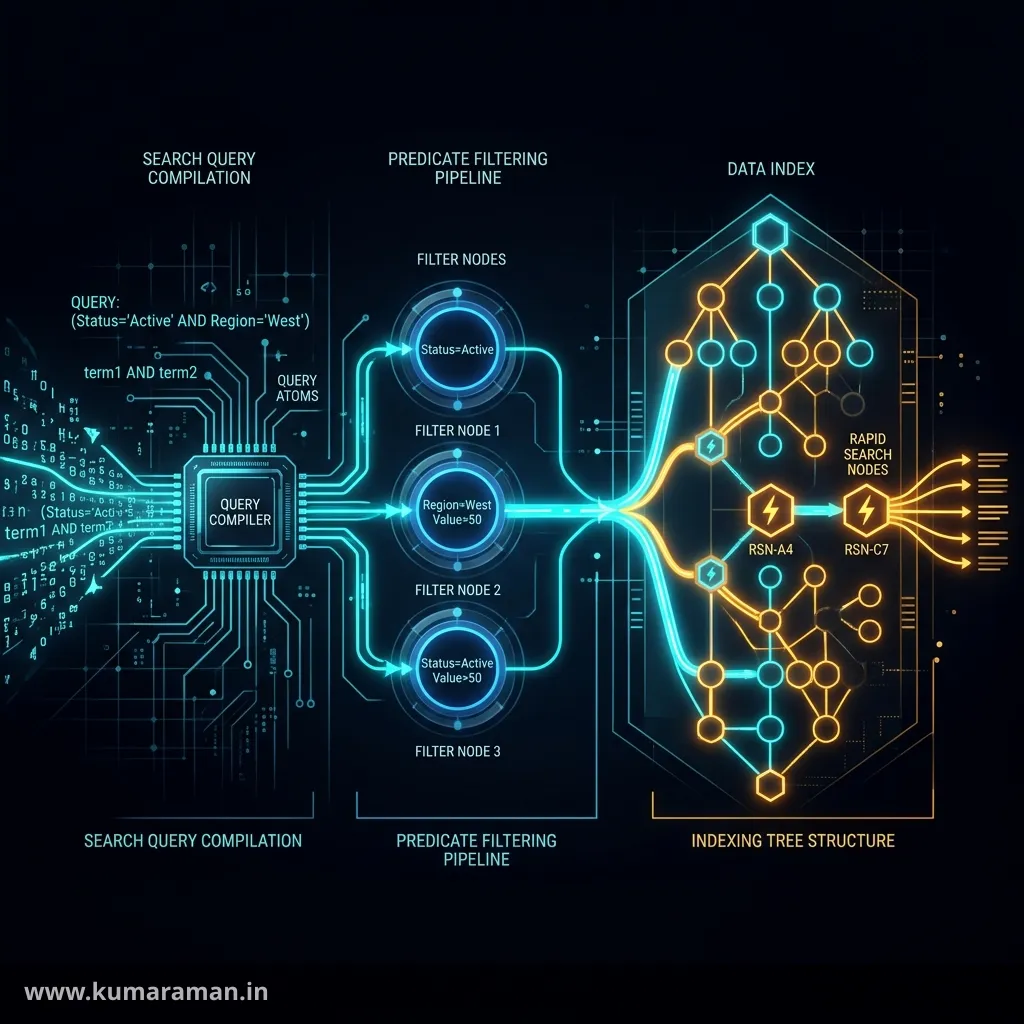
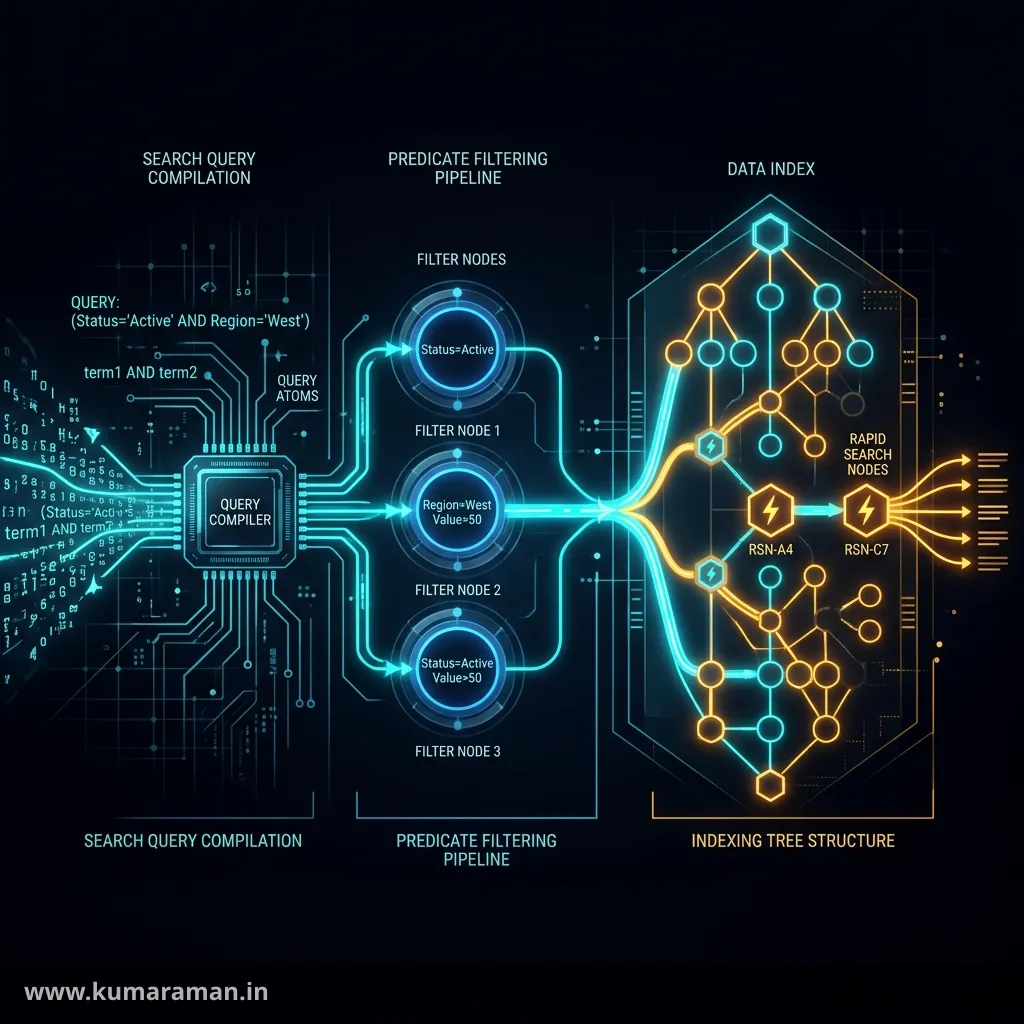
The Query Builder is an AEM API in the com.day.cq.search package. In Adobe's words, the server-side QueryBuilder "accepts a query description, create[s] and run[s] an XPath query, optionally filter[s] the result set, and also extract[s] facets." The query description is a tree of predicates, and every predicate type is handled by a predicate evaluator, an OSGi component that knows how to turn that predicate into an XPath fragment, into a row-by-row filter, or both.
So a Query Builder query goes through several layers before any content is read:
path=/content/site            ┐
type=cq:Page                  │  predicates (map / HTTP params)
property=jcr:content/cq:template
property.value=/conf/...      ┘
        │
        ▼  predicate evaluators (one per predicate type)
/jcr:root/content/site//element(*, cq:Page)[jcr:content/@cq:template = '/conf/...']
        │
        ▼  Oak converts XPath to JCR-SQL2 internally
select ... from [cq:Page] as a where ... isdescendantnode(a, '/content/site')
        │
        ▼  Oak query engine picks the cheapest index (or traverses)
index rows → access-control check → Query Builder filtering predicates → hits
Most Query Builder performance problems come from ignoring two consequences:
- The Query Builder is only as fast as the XPath it generates. If Oak can't serve that XPath from an index, it traverses.
- Some predicates never reach Oak. Filtering predicates run in Java after Oak returns rows, so Oak still reads every row they later discard.
The Oak docs confirm the middle step: XPath queries "are internally converted to SQL-2," with or conditions turned into union queries so each branch can use an index. Adobe calls the conversion overhead "minimal," so choosing a language is about readability and tooling, not speed.
When to use the Query Builder vs JCR-SQL2 directly
| Use the Query Builder when… | Use JCR-SQL2 (or XPath) directly when… |
|---|---|
| The query is built from user or UI input (search forms, filters, facets) | You want the exact statement you'll see in Explain Query, with no translation layer |
You want paging metadata (total, more, offset) for free | You need a feature the predicates don't express cleanly |
| You want facets (counts per tag, type, date bucket) | You're writing a one-off script or migration and want full control |
| You want reusable domain predicates via a custom evaluator | You want to avoid AEM-specific APIs (plain JCR or Sling findResources) |
Adobe's 6.5 best-practices guide marks QueryBuilder and XPath as "recommended" and lists SQL-2 without that label. Either way, the index rules are identical.
The HTTP endpoint and the debugger
The Query Builder is exposed over HTTP by a JSON servlet:
http://localhost:4502/bin/querybuilder.json?path=/content/wknd&type=cq:Page&p.limit=5Every predicate is simply a request parameter. The response is JSON with paging metadata and the hits:
{
  "success": true,
  "results": 5,
  "total": 148,
  "more": false,
  "offset": 0,
  "hits": [ { "path": "/content/wknd/us/en", "title": "WKND", "...": "..." } ]
}
For interactive work, use the Query Builder Debugger at:
http://localhost:4502/libs/cq/search/content/querydebug.htmlPaste predicates one per line, run them, and the debugger shows the hits and the generated XPath, which you copy into Explain Query to see which index Oak uses. The path is the same on AEM 6.5 and the Cloud Service SDK.
Important: The servlet returns 10 hits by default.
p.limit=-1returns everything, which is fine for a debugger session on your laptop and a bad idea anywhere else.
Why /bin/querybuilder.json must be blocked on publish
The servlet runs with the permissions of the calling user. On publish, that's usually anonymous, which can typically read all of /content. An open endpoint therefore gives anyone on the internet two things:
- Data exposure. Arbitrary queries, plus
p.hits=fullandp.nodedepth=0, return every property of every readable node, including properties you never render. - Denial of service.
path=/&p.limit=-1, unindexed queries, and huge offsets are cheap to send and expensive to answer.
Block it at the Dispatcher. The Adobe-provided default filter sets start from "deny everything," so the endpoint is closed unless someone opens it. The usual way it gets reopened is a broad allow rule such as /bin/*. On a classic dispatcher.any, an explicit deny near the end of the filter section makes the intent obvious:
/filter {
  # ... deny-all first, then narrow allows ...
  /0900 { /type "deny" /url "/bin/querybuilder*" }
  # Sling's query servlet: .query.json selector
  /0901 { /type "deny" /selectors '((sys|doc)view|query|[0-9-]+)' /extension '(json|xml)' }
}
Adobe has also published a KB article about encoded-slash and ; variants (for example /%2fbin%2fquerybuilder.json or /bin/querybuilder.json;x) getting past Dispatcher filters on AEM as a Cloud Service. The documented fix blocks those at the Apache level:
<LocationMatch "(?i)/(etc/truststore.json|bin/querybuilder.json)(;|%3B)">
    ProxyPass "!"
</LocationMatch>
Add both probes to your Dispatcher test suite. The Dispatcher Tester can run them as a batch.
Tip: If publish needs search, write a dedicated servlet that accepts whitelisted parameters, builds the predicate map server-side with a capped
p.limitandp.guessTotal, and returns only the fields the UI needs.
On author, results are filtered by the logged-in user's ACLs. Adobe's 6.5 KB on QueryBuilderImpl resolver warnings also recommends blocking external access to /bin/querybuilder in production.
Query syntax: the rules of the map
A Query Builder query is a flat map of strings. A handful of rules explain almost everything:
- Predicate name = key.
path=/content/siteadds apathpredicate whose main value is/content/site. - Predicate parameters use a dot.
property.value=...,path.flat=true,orderby.sort=desc. - Principal parameter shorthand. Each evaluator has a principal parameter named after the predicate, so
similar=/content/enis short forsimilar.similar=/content/en. All other parameters must be written in full. - Repeat a predicate with a numeric prefix.
1_property=...and2_property=...are two independent property predicates. Adobe notes that you cannot reuse the same numeric prefix in one query, even across different predicate types. - Everything is ANDed by default. The whole query lives inside an implicit root group, and groups AND their children unless told otherwise.
p.means "parameter of the group."group.p.or=truesets a parameter on the group, whilegroup.1_path=...adds a child predicate to it.
Root parameters
These live on the implicit root group and control paging and output:
| Parameter | What it does |
|---|---|
p.offset | How many results to skip (start of the page). Default 0. |
p.limit | Page size. Servlet default is 10; -1 means all results. |
p.guessTotal | Avoid counting the full result. true counts only up to p.offset + p.limit; a number (e.g. 100) counts up to that maximum. |
p.excerpt | true includes a full-text excerpt in each hit. |
p.hits | JSON servlet only. How hits are written: simple, full, or selective. |
p.properties | For p.hits=selective: space-separated relative paths (use + in URLs). jcr:path returns the hit's path. |
p.nodedepth | For p.hits=full: how many child levels to include; 0 means the entire subtree. |
p.acls | For p.hits=full: true adds the current session's permissions on each hit. |
p.indexTag | Adds an Oak index-tag option to the generated query (documented in the Cloud Service reference). |
p.facetStrategy | oak delegates facet extraction to Oak (documented in the Cloud Service reference). |
simple (the default) returns minimal fields such as path, title, and lastmodified. full is the Sling JSON rendering of each node, and selective returns only what you list, with deeper relative paths nested as child objects:
path=/content/wknd
type=cq:Page
p.hits=selective
p.properties=jcr:path jcr:content/jcr:title jcr:content/cq:lastModified
p.limit=20
Note:
p.indexTagandp.facetStrategyappear in the AEM as a Cloud Service predicate reference but not in the 6.5 reference. If you're on 6.5, test them on your service pack before depending on them.
Ordering
orderby sorts either by a JCR property (prefixed with @) or by another predicate in the query:
type=cq:Page
path=/content/wknd
orderby=@jcr:content/cq:lastModified
orderby.sort=descorderby.sortisasc(default) ordesc.orderby.case=ignoremakes the sort case-insensitive.- For multiple sort keys, repeat with prefixes:
1_orderby=@jcr:content/jcr:title,2_orderby=@jcr:created. orderby=@jcr:scorewithorderby.sort=descgives relevance order for full-text searches.
Ordering is a performance decision. Oak can only return results already sorted if the ordering property is indexed with ordered=true. Otherwise the whole result set is read into memory and sorted. Adobe's own debug-log example shows a Query Builder orderby being handled by a "custom order by comparator" in memory, and the Cloud Service best-practices page lists "Comparator-based sorting in QueryBuilder" as a known cause of index traversal.
The predicate reference
Every predicate below is in Adobe's current Query Builder Predicate Reference. Where Adobe documents a predicate as filtering-only, it's called out. Those can't use an index, so pair them with index-friendly predicates that narrow the result first.
path
Restricts results to a location. It's the cheapest way to shrink a query, and almost every query should have one.
| Parameter | Meaning |
|---|---|
path | The path. By default matches all descendants (like //* in XPath), not the base node itself. |
path.exact | true: the path must match exactly; simple * wildcards match names but not /. |
path.flat | true: direct children only (like /* in XPath). Ignored if exact is true. |
path.self | Include the base node in the subtree. Deprecated on Cloud Service (see below). |
# direct children of the language root only
path=/content/wknd/us/en
path.flat=true
type=cq:Page
Important: Adobe's Cloud Service reference now flags
path.selfas deprecated: "An issue has been identified withselfproperty … using it in queries may not produce correct search results," and the implementation won't be changed because apps depend on it. Avoid it. If you need the base node, fetch it directly by path.
To search several paths, put multiple path predicates in an OR group (see group).
type
Restricts results to a node type or mixin, including subtypes. Common values are cq:Page, dam:Asset, cq:PageContent, and nt:unstructured.
type=dam:Asset
path=/content/dam/wknd
The type matters for performance: OOTB Lucene indexes are organized by node type (damAssetLucene only covers dam:Asset), so nt:base or nt:unstructured queries rarely hit a well-shaped index.
nodename
Matches node names with wildcards: * is any or no characters, ? is exactly one character, and [abc] is one of the bracketed characters.
type=nt:file
nodename=*.jar
orderby=@jcr:content/jcr:lastModified
orderby.sort=desc
Adobe's own debug-log example for this exact query shows nodename=*.jar listed under filtering predicates, with the XPath reduced to //element(*, nt:file). In other words, every nt:file in the repository is read and then filtered in Java. Always pair nodename with a tight path.
property
The workhorse predicate. It matches JCR properties, and relative paths are allowed (jcr:content/cq:template).
| Parameter | Meaning |
|---|---|
property | Relative path to the property |
property.value | Value to match (converted per JCR property type) |
property.N_value | Multiple values: 1_value, 2_value, … (OR by default) |
property.and | true: all N_values must match (useful for multi-value properties) |
property.operation | equals (default), unequals, like, not, exists |
property.depth | Number of wildcard levels the property may sit under |
The operations:
equals/unequals: exact match or inequality.like: uses the XPathjcr:likefunction. Use%as the wildcard, e.g.property.value=/apps/wknd/components/%.not: the property must not exist (not(@prop)).valueis ignored.exists: existence check. Pair it withproperty.value=true(must exist) orfalse(same asnot). Set the value explicitly: the Javadoc and the Cloud Service reference page describe the default differently.
The Javadoc for JcrPropertyPredicateEvaluator also lists equalsIgnoreCase and unequalsIgnoreCase. They aren't on the predicate reference page, so run them through Explain Query before relying on them.
# pages using either of two templates (OR across values)
path=/content/wknd
type=cq:Page
property=jcr:content/cq:template
property.1_value=/conf/wknd/settings/wcm/templates/article-page
property.2_value=/conf/wknd/settings/wcm/templates/adventure-page

# multi-value: tagged with BOTH values
property=jcr:content/cq:tags
property.and=true
property.1_value=wknd:activity/cycling
property.2_value=wknd:region/europe

# any depth-2 descendant with a 'size' property
property=size
property.depth=2
A detail from the official examples trips people up: type=cq:PageContent with property=cq:template returns the jcr:content nodes, not the pages. Query for type=cq:Page with property=jcr:content/cq:template to get the pages themselves.
fulltext
Searches the full-text index, which maps to jcr:contains() in XPath. Its parameters are fulltext (the terms) and the optional fulltext.relPath (search a specific property or subnode).
path=/content/wknd
type=cq:Page
fulltext=mountain biking
fulltext.relPath=jcr:content
orderby=@jcr:score
orderby.sort=desc
p.excerpt=true
It can't run as a filter, so it depends entirely on a full-text Lucene index that covers the node type and path.
daterange
Matches a DATE property against an interval. Bounds are ISO 8601 (partial forms like 2026-01-01 are fine) or POSIX time.
| Parameter | Meaning |
|---|---|
daterange.property | Relative path to a DATE property |
daterange.lowerBound / daterange.upperBound | The interval |
daterange.lowerOperation | > (default) or >= |
daterange.upperOperation | < (default) or <= |
daterange.timeZone | Time zone ID when the bound isn't a full ISO string |
type=cq:Page
path=/content/wknd
daterange.property=jcr:content/cq:lastModified
daterange.lowerBound=2026-01-01
daterange.lowerOperation=>=
relativedaterange
Like daterange, but the bounds are offsets from the current server time, written in milliseconds or Bugzilla syntax: 1s 2m 3h 4d 5w 6M 7y. Prefix with - for the past. If you set only one bound, the other defaults to 0 (now). It inherits property from daterange.
# modified in the last 7 days
type=cq:Page
path=/content/wknd
relativedaterange.property=jcr:content/cq:lastModified
relativedaterange.lowerBound=-7d
It ignores leap years and treats every month as 30 days.
tagid and tag
Both search for tagged content. The property defaults to cq:tags, so for pages you need jcr:content/cq:tags.
tagid: by tag ID, e.g.wknd:activity/cycling. Prefer this. IDs are stable, titles aren't.tag: by tag title path.- Both support
N_value(OR by default, AND withand=true) andproperty.
type=cq:Page
path=/content/wknd
tagid=wknd:activity/cycling
tagid.property=jcr:content/cq:tags
There's also tagsearch, which first finds tags whose titles contain a keyword and then returns content tagged with them. Its parameters are tagsearch, property, lang for a localized title, and all to search all tag text.
boolproperty
Matches properties of JCR type Boolean (not the string "true" many dialogs store) with value set to true or false. When the value is false, it also matches nodes where the property doesn't exist, which makes it good for opt-in flags.
boolproperty=jcr:content/myFeatureEnabled
boolproperty.value=true
rangeproperty
Matches linear types (LONG, DOUBLE, DECIMAL) against an interval. The parameters are property, lowerBound, lowerOperation (> default or >=), upperBound, upperOperation (< default or <=), and decimal=true for Decimal properties. For dates, use daterange.
type=dam:Asset
rangeproperty.property=jcr:content/metadata/tiff:ImageWidth
rangeproperty.lowerBound=2000
rangeproperty.lowerOperation=>=
group
Groups build nested boolean logic. Think of them as parentheses.
| Parameter | Meaning |
|---|---|
group.p.or | true: only one child must match (OR). Default AND. |
group.p.not | true: negate the whole group. |
group.<predicate> / group.N_<predicate> | Child predicates |
# "Experience" AND (under magazine OR under adventures)
fulltext=Experience
group.p.or=true
group.1_path=/content/wknd/us/en/magazine
group.2_path=/content/wknd/us/en/adventures
Groups can nest. This is fulltext AND ((path AND type) OR (path AND type)):
fulltext=Management
group.p.or=true
group.1_group.path=/content/wknd/ch/de
group.1_group.type=cq:Page
group.2_group.path=/content/dam/wknd
group.2_group.type=dam:Asset
Negation, for all pages except those in an archive branch:
type=cq:Page
path=/content/wknd
group.p.not=true
group.path=/content/wknd/archive
Adobe's warning applies here: "Such OR joins need good indexes for performance reasons." Oak turns ORs into UNIONs, so each branch must be indexable on its own.
Filtering-only predicates
Adobe documents each of these as "a filtering-only predicate and cannot use a search index," so use them only on an already narrow query.
| Predicate | Parameters | Use |
|---|---|---|
excludepaths | regex | Drop results whose path matches a regex |
hasPermission | comma-separated privileges, e.g. jcr:write | Only items the current session has those privileges on |
language | ISO code, e.g. de | Pages in a language (checks the language property and the path) |
mainasset | true / false | DAM main assets vs sub-assets |
memberOf | path of a Sling resource collection | Items in a collection |
dateComparison | property1, property2, operation (=, !=, >, >=) | Compare two date properties on the same node |
dateComparison is handy for "modified since last publish" reports (it returns jcr:content nodes here). Scope it hard:
path=/content/wknd/us/en
type=cq:PageContent
dateComparison.property1=cq:lastModified
dateComparison.property2=cq:lastReplicated
dateComparison.operation=>
The remaining predicates
similar: similarity search via XPathrep:similar().similaris the absolute path of the reference node, andsimilar.localis a relative descendant (default.). Explain it before relying on it.savedquery: pulls in all predicates of a query stored withQueryBuilder#storeQuery()(a multi-line String property or annt:file) as a sub-group. It extends the current query rather than running a second one.notexpired: withnotexpired=true|falseplusproperty(aDATEproperty), it keeps items whose date is still in the future (or already past).contentfragment: restricts results to Content Fragments. Any value works (contentfragment=true).- Excerpts aren't a predicate. They're the root parameter
p.excerpt=true, read in Java viaHit.getExcerpt()/getExcerpts().
The Java API
The same map drives the Java API. Get QueryBuilder as an OSGi reference (or via resourceResolver.adaptTo(QueryBuilder.class) in a Sling Model), build a PredicateGroup, create a Query with a JCR Session, and read the SearchResult.
@Component(service = TemplateUsageService.class)
public class TemplateUsageService {

    @Reference
    private QueryBuilder queryBuilder;

    public List<String> findPagesByTemplate(ResourceResolver resolver, String root, String template) {
        Map<String, String> map = new HashMap<>();
        map.put("path", root);
        map.put("type", "cq:Page");
        map.put("property", "jcr:content/cq:template");
        map.put("property.value", template);
        map.put("p.limit", "100");        // same as query.setHitsPerPage(100)
        map.put("p.guessTotal", "true");  // don't count the whole result

        Session session = resolver.adaptTo(Session.class);
        Query query = queryBuilder.createQuery(PredicateGroup.create(map), session);
        SearchResult result = query.getResult();

        List<String> paths = new ArrayList<>();
        for (Hit hit : result.getHits()) {
            try {
                paths.add(hit.getPath());
            } catch (RepositoryException e) {
                // log and continue
            }
        }
        return paths;
    }
}
The key types and the methods you'll actually use:
| Type | Methods |
|---|---|
QueryBuilder | createQuery(PredicateGroup, Session), createQuery(Session), storeQuery(...), loadQuery(path, session) |
PredicateGroup | PredicateGroup.create(Map), add(Predicate), setAllRequired(boolean), setNegated(boolean) |
Query | setStart(long), setHitsPerPage(long), setGuessTotal(boolean) / setGuessTotal(long), setExcerpt(boolean), getResult(), registerPredicateEvaluator(type, evaluator), refine(Bucket) |
SearchResult | getHits(), getResources(), getNodes(), getTotalMatches(), hasMore(), getStartIndex(), getQueryStatement(), getFilteringPredicates(), getExecutionTimeMillis(), getFacets() |
Hit | getPath(), getResource(), getNode(), getProperties(), getExcerpt(), getScore(), getIndex() |
A few details matter more than they look:
setHitsPerPage(0)means unlimited in Java. The HTTP equivalent isp.limit=-1. The Java default is 10, like the servlet.getResult()is cached. A second call returns the same result, so build a newQueryto re-run it.hit.getProperties()returns thejcr:contentproperties if that child exists, otherwise the node's own.getQueryStatement()returns the generated XPath andgetFilteringPredicates()lists what ran as a filter. Log both while developing.
The cost of the total count
By default the Query Builder calculates the total number of hits. Adobe spells out why this is expensive: "determining the accurate count involves checking every result for access control," and on Oak it means reading the entire result set. A query that shows 20 hits per page but matches 200,000 nodes has to read every match to count it, and can run into Oak's read limit doing so.
p.guessTotal (or query.setGuessTotal(...)) fixes this, and Adobe recommends it as the pagination strategy:
p.limit=10
p.guessTotal=100
total=43, more=false: the exact total is 43, so show "43 results".total=100, more=true: there are more than 100, so show "100+ results" and raiseguessTotalas the user pages.
Use p.guessTotal=true for infinite scroll, where you only need to know whether there's a next page.
The ResourceResolver leak gotcha
This is the long-standing Query Builder trap. You pass in a Session, but Hit.getResource() returns a Resource, so the Query Builder works with its own internal ResourceResolver, and according to Adobe's KB and the ACS AEM Samples project, that resolver isn't closed for you. Symptoms include Unclosed ResourceResolver warnings attributed to com.day.cq.search.impl.builder.QueryBuilderImpl and, in long-running code, resolver pile-up.
Adobe's KB article (written for AEM 6.5) documents a workaround: close the internal resolver after processing, via the first resource from result.getResources(). The ACS AEM Samples project does the same with a try/finally around the hit loop. A defensive version that won't close your own resolver by mistake:
SearchResult result = query.getResult();
ResourceResolver qbResolver = null;
try {
    for (Hit hit : result.getHits()) {
        Resource resource = hit.getResource();
        if (qbResolver == null) {
            qbResolver = resource.getResourceResolver();   // Query Builder's internal resolver
        }
        // read everything you need from `resource` here
    }
} catch (RepositoryException e) {
    // log
} finally {
    // myResolver = the resolver you opened and passed in (as a Session)
    if (qbResolver != null && qbResolver != myResolver && qbResolver.isLive()) {
        qbResolver.close();
    }
}
The identity check matters: never close a resolver you don't own by accident. For resolvers created around an existing JCR session, Sling documents that closing the resolver does not log out that session. The cleaner pattern is to not use the Query Builder's resources at all. Take hit.getPath() and resolve it with your own resolver (myResolver.getResource(path)), which you already manage with try-with-resources. Then the lifecycle is yours and the resources stay valid after the loop.
Note: An Experience League community thread reports the warning on 6.5.12 even with empty results when the
tagidpredicate is used, and Adobe's answer was that it's a known product issue. Adobe hasn't documented whether AEM as a Cloud Service still leaks, so check your logs rather than assuming either way.
Get resolvers from a service user via getServiceResourceResolver (never loginAdministrative) and close them with try-with-resources. The Security guide covers service-user mapping.
Custom predicate evaluators
When the same cluster of predicates keeps recurring, or you need logic XPath can't express, write a custom predicate evaluator: an OSGi component factory named com.day.cq.search.eval.PredicateEvaluator/ plus the predicate name you'll use in queries.
Extend AbstractPredicateEvaluator. Its defaults do nothing: getXPathExpression returns null, canXpath returns true, canFilter returns false, and includes returns true. You override one of two paths:
| Approach | Override | Runs | Performance |
|---|---|---|---|
| XPath evaluator | getXPathExpression(Predicate, EvaluationContext) | Inside the Oak query (index-capable) | Good, if the index covers it |
| Filtering evaluator | canXpath → false, canFilter → true, includes(Predicate, Row, EvaluationContext) | Row by row, after Oak | The Javadoc warns it's "more likely to negatively impact performance" |
An XPath evaluator based on Adobe's replication-metadata example, using DS annotations (which work on AEM as a Cloud Service and modern 6.5 builds):
import com.day.cq.search.Predicate;
import com.day.cq.search.eval.AbstractPredicateEvaluator;
import com.day.cq.search.eval.EvaluationContext;
import org.osgi.service.component.annotations.Component;

@Component(factory = "com.day.cq.search.eval.PredicateEvaluator/replic")
public class ReplicationPredicateEvaluator extends AbstractPredicateEvaluator {

    @Override
    public String getXPathExpression(Predicate predicate, EvaluationContext context) {
        StringBuilder xpath = new StringBuilder();
        append(xpath, "jcr:content/@cq:lastReplicatedBy", predicate.get("by"));
        append(xpath, "jcr:content/@cq:lastReplicationAction", predicate.get("action"));

        String since = predicate.get("since");
        if (since != null) {
            and(xpath).append("jcr:content/@cq:lastReplicated >= xs:dateTime('")
                      .append(escape(since)).append("')");
        }
        return xpath.length() == 0 ? null : xpath.toString();
    }

    private void append(StringBuilder sb, String prop, String value) {
        if (value != null) {
            and(sb).append(prop).append(" = '").append(escape(value)).append("'");
        }
    }

    private StringBuilder and(StringBuilder sb) {
        return sb.length() > 0 ? sb.append(" and ") : sb;
    }

    private String escape(String value) {
        return value.replace("'", "''");   // XPath string literal escaping
    }
}
Usage:
path=/content/wknd
type=cq:Page
replic.by=admin
replic.action=Activate
replic.since=2026-01-01T00:00:00.000Z
The expression you return is a partial XPath predicate, the part that goes inside [ and ], relative to the result node. Always escape values: an evaluator that concatenates raw HTTP input is an injection point.
A filtering evaluator, in the style of ACS AEM Commons' nodeExists predicate:
@Component(factory = "com.day.cq.search.eval.PredicateEvaluator/hasChild")
public class HasChildPredicateEvaluator extends AbstractPredicateEvaluator {

    @Override
    public boolean canXpath(Predicate predicate, EvaluationContext context) {
        return false;
    }

    @Override
    public boolean canFilter(Predicate predicate, EvaluationContext context) {
        return predicate.get("hasChild") != null;
    }

    @Override
    public boolean includes(Predicate predicate, Row row, EvaluationContext context) {
        try {
            return row.getNode().hasNode(predicate.get("hasChild"));
        } catch (RepositoryException e) {
            return false;
        }
    }
}
Also available: getOrderByProperties (preferred for sorting) vs getOrderByComparator (in-memory, avoid), getFacetExtractor for facets, and query.registerPredicateEvaluator("type", evaluator) to register an evaluator for a single query without OSGi. Test evaluators with AEM Mocks (see the unit testing guide).
Note: Adobe's docs still show Felix SCR annotations (
org.apache.felix.scr.annotations.Componentwithmetatype = false). SCR annotations are obsolete in current Maven builds, so useorg.osgi.service.component.annotations.Componentwith the samefactoryvalue. The annotations reference covers the migration.
Performance: making Query Builder queries fast
The JCR & Oak guide's indexing advice applies in full. What's Query Builder-specific is finding and fixing the XPath it generates.
Step 1: Get the XPath
There are two ways, both from Adobe's docs:
- Debugger: run the predicates in
/libs/cq/search/content/querydebug.htmland copy the generated XPath. - Logging: create a DEBUG logger for
com.day.cq.search.impl.builder.QueryImpl. It logs the predicate tree, the XPath, any filtering predicates or comparator, and the execution time:
QueryImpl XPath query: //element(*, nt:file)
QueryImpl filtering predicates: {nodename=nodename: nodename=*.jar}
QueryImpl custom order by comparator: jcr:content/jcr:lastModified
QueryImpl query execution took 272 ms
A filtering predicates or custom order by comparator line is a red flag: work is happening in Java after Oak has already read the rows.
Step 2: Explain it
Paste the XPath (choose XPath as the language) into Explain Query:
- AEM 6.5: Tools → Operations → Diagnosis → Query Performance → Explain Query tab.
- AEM as a Cloud Service: the Query Performance tool (
/libs/granite/operations/content/diagnosistools/queryPerformance.html), reachable from the Developer Console in Cloud Manager. Adobe notes that it shows more execution detail than the 6.x version, including a Read Optimization score (rows scanned vs. rows returned; 90%+ is well indexed) and "Slow Queries" (currently defined as reading or scanning more than 5,000 rows).
In the plan, check that every restriction appears inside the index query. In the Lucene syntax that looks like +:ancestors:/content/dam for the path and +jcr:content/metadata/dc:title:… for a property. Any restriction that appears only in the trailing where clause is filtered in the query engine. The fix is to add that property to a custom version of the OOTB index (e.g. damAssetLucene-<n>-custom-<m> on Cloud Service) rather than creating a competing index.
Step 3: Respect the limits
Oak can stop runaway queries. The Oak defaults are unlimited, but AEM configures them (preconfigured since 6.3 via the QueryEngineSettings OSGi config / JMX LimitReads and LimitInMemory):
| Setting | AEM value | What you see |
|---|---|---|
queryLimitReads | 100,000 | The query read or traversed more than 100000 nodes. To avoid affecting other tasks, processing was stopped. |
queryLimitInMemory | 500,000 | The query read more than 500000 nodes in memory. To avoid running out of memory, processing was stopped |
Cloud Service docs describe the same 100,000-node traversal limit. Adobe's 6.5 guidance is to set both much lower in development (e.g. 10,000 in memory, 5,000 reads) so expensive queries fail on your laptop, not in production.
Adobe's Cloud Service page also lists the Query Builder-specific causes of index traversal, which is the best checklist available:
| Cause | Mitigation |
|---|---|
No p.guessTotal (or a very large one) | Set p.guessTotal to a sensible value |
p.limit=-1 or a huge limit | Keep p.limit at 1000 or below |
| A filtering predicate discarding many rows | Replace it with a restriction the JCR query can apply |
| Comparator-based sorting | Order by a property indexed with ordered=true |
| ACLs filtering out many results | Add path or property restrictions that mirror the ACLs |
Large p.offset | Use keyset pagination |
| Wrong index chosen | Use index tags (p.indexTag + selectionPolicy=tag) |
For genuinely large result sets, Adobe advises running the query in a Sling Job or workflow, not a request, and using Oak keyset pagination: order by an indexed key and fetch "greater than the last key seen" per batch.
Query Builder vs JCR-SQL2 vs XPath
| Query Builder | JCR-SQL2 | XPath | |
|---|---|---|---|
| Shape | Key/value predicates | SQL-like statement | Path expression |
| Executed as | XPath → converted to SQL-2 | SQL-2 (native to Oak) | Converted to SQL-2 |
| Java entry point | QueryBuilder.createQuery(...) | QueryManager.createQuery(stmt, Query.JCR_SQL2) / resolver.findResources(...) | Same, with Query.XPATH (deprecated in JCR 2.0 but supported by Oak) |
| HTTP | /bin/querybuilder.json | Sling's .query.json selector (block on publish) | Same (block on publish) |
| Paging / total | Built in (p.offset, p.limit, total, more, p.guessTotal) | setLimit / setOffset; count by iterating | Same as SQL-2 |
| Extensibility | Custom predicate evaluators | None | None |
| Hidden costs | Total count, filtering predicates, comparator sorting | What you write is what runs | What you write is what runs |
| Best for | Search UIs, facets, form-driven queries | Precise, hand-tuned, one-off queries | Reading what the Query Builder generates |
Real-world recipes
Explain each of these on your own content before shipping it. Index coverage depends on your index definitions, not on the Query Builder.
Find pages by template
path=/content/wknd
type=cq:Page
property=jcr:content/cq:template
property.value=/conf/wknd/settings/wcm/templates/article-page
p.hits=selective
p.properties=jcr:path jcr:content/jcr:title
p.limit=100
p.guessTotal=true
Find assets missing a title
path=/content/dam/wknd
type=dam:Asset
property=jcr:content/metadata/dc:title
property.operation=not
p.hits=selective
p.properties=jcr:path
p.limit=200
A "property does not exist" restriction can only be answered by a Lucene index if that property definition has nullCheckEnabled=true. Otherwise Oak reads every asset under the path and checks each one. If Explain shows the restriction outside the index query, add the property (with nullCheckEnabled) to a custom damAssetLucene version.
Pages modified in the last 7 days
path=/content/wknd
type=cq:Page
relativedaterange.property=jcr:content/cq:lastModified
relativedaterange.lowerBound=-7d
orderby=@jcr:content/cq:lastModified
orderby.sort=desc
p.limit=50
p.guessTotal=100
Find components that reference an asset
path=/content/wknd
type=nt:unstructured
property=fileReference
property.value=/content/dam/wknd/en/adventures/hero.jpg
p.hits=selective
p.properties=jcr:path sling:resourceType
p.limit=100
This finds components using the conventional fileReference property; add other property names as N_property entries in an OR group. Explain it carefully, because broad nt:unstructured queries under /content are a classic source of traversal.
The AEM Query & Report Builder generates these reports (page finder, template and component usage, asset audits) and gives you the Query Builder, SQL-2, XPath, and Java versions of each.
Cheat sheet
| Need | Query Builder |
|---|---|
| Test a query | /libs/cq/search/content/querydebug.html |
| HTTP endpoint (author only) | /bin/querybuilder.json?... |
| Descendants of a path | path=/content/site |
| Direct children only | path=/content/site + path.flat=true |
| Node type | type=cq:Page / type=dam:Asset |
| Property equals | property=jcr:content/x + property.value=y |
| Property OR values | property.1_value=a + property.2_value=b |
| Property doesn't exist | property.operation=not |
| OR across predicates | group.p.or=true + group.1_..., group.2_... |
| Full-text | fulltext=term (+ fulltext.relPath) |
| Date window | daterange.property, lowerBound, upperBound |
| Last N days | relativedaterange.lowerBound=-7d |
| Tag by ID | tagid=ns:tag + tagid.property=jcr:content/cq:tags |
| Sort | orderby=@prop + orderby.sort=desc |
| Cheap totals | p.guessTotal=true or p.guessTotal=100 |
| Only some properties | p.hits=selective + p.properties=a b |
| See generated XPath | DEBUG logger com.day.cq.search.impl.builder.QueryImpl |
| Explain plan | Explain Query (6.5 Operations / Cloud Developer Console) |
| Custom predicate | @Component(factory = "com.day.cq.search.eval.PredicateEvaluator/name") |
Best practices
- ✅ Always set a
pathand a specifictype, the two cheapest restrictions. - ✅ Always set
p.limit(ideally 1,000 or below) andp.guessTotal. - ✅ Explain every query during development with the XPath from the debugger or the
QueryImpllog. - ✅ Prefer indexed restrictions over filtering-only predicates, and only filter an already narrow set.
- ✅ Order by properties that are indexed as ordered.
- ✅ Extend OOTB indexes (custom versions) rather than adding competing ones.
- ✅ Run large or unbounded queries in Sling Jobs with keyset pagination, not in requests.
- ✅ Keep queries out of component rendering. Precompute, cache, or navigate by path.
Do's and Don'ts
Do
- ✅ Block
/bin/querybuilder.json(and.query.json) on publish, including the encoded and;variants. - ✅ Build a dedicated, whitelisted servlet if publish needs search.
- ✅ Use
tagid(stable IDs) rather thantag(titles). - ✅ Resolve hits with your own resolver via
hit.getPath(), or close the Query Builder's internal resolver. - ✅ Escape values inside custom XPath evaluators.
Don't
- ❌ Don't ship
p.limit=-1to production code. - ❌ Don't let the Query Builder count totals you'll never display.
- ❌ Don't use
path.self. It's deprecated and can return wrong results. - ❌ Don't rely on
nodename,excludepaths,language, orhasPermissionto narrow a large result set, since they filter after the fact. - ❌ Don't use big
p.offsetvalues for deep paging. Use keyset pagination. - ❌ Don't reuse the same numeric prefix twice in one query.
Wrapping up
The Query Builder is a convenience layer: predicates in, XPath out, Oak does the real work. Keep that model in mind and most of its behavior becomes predictable. Every query needs a path, a type, a limit, and p.guessTotal. Filtering predicates and comparator sorting run in Java after Oak has already read the rows. The only way to know a query is healthy is to take the generated XPath and explain it against your real indexes. Lock the HTTP endpoint away from publish, manage resolvers deliberately in Java, and use custom evaluators when they make queries clearer.
The official references worth bookmarking are Adobe's Query Builder API and Predicate Reference pages, the Query and Indexing Best Practices guide, and the Oak query engine documentation.
Continue with the JCR & Oak repository guide for index definitions and JCR-SQL2, the Performance & Troubleshooting guide for finding slow queries in production, the Dispatcher guide for filter rules, and the AEM Developer Cheat Sheet for quick references. When you need a report today, the AEM Query & Report Builder writes the query for you.
Discussion
Loading discussion…
Try a related tool
Subscribe to the Newsletter
Get the latest articles, tutorials, and tech insights delivered straight to your inbox. No spam, unsubscribe anytime.