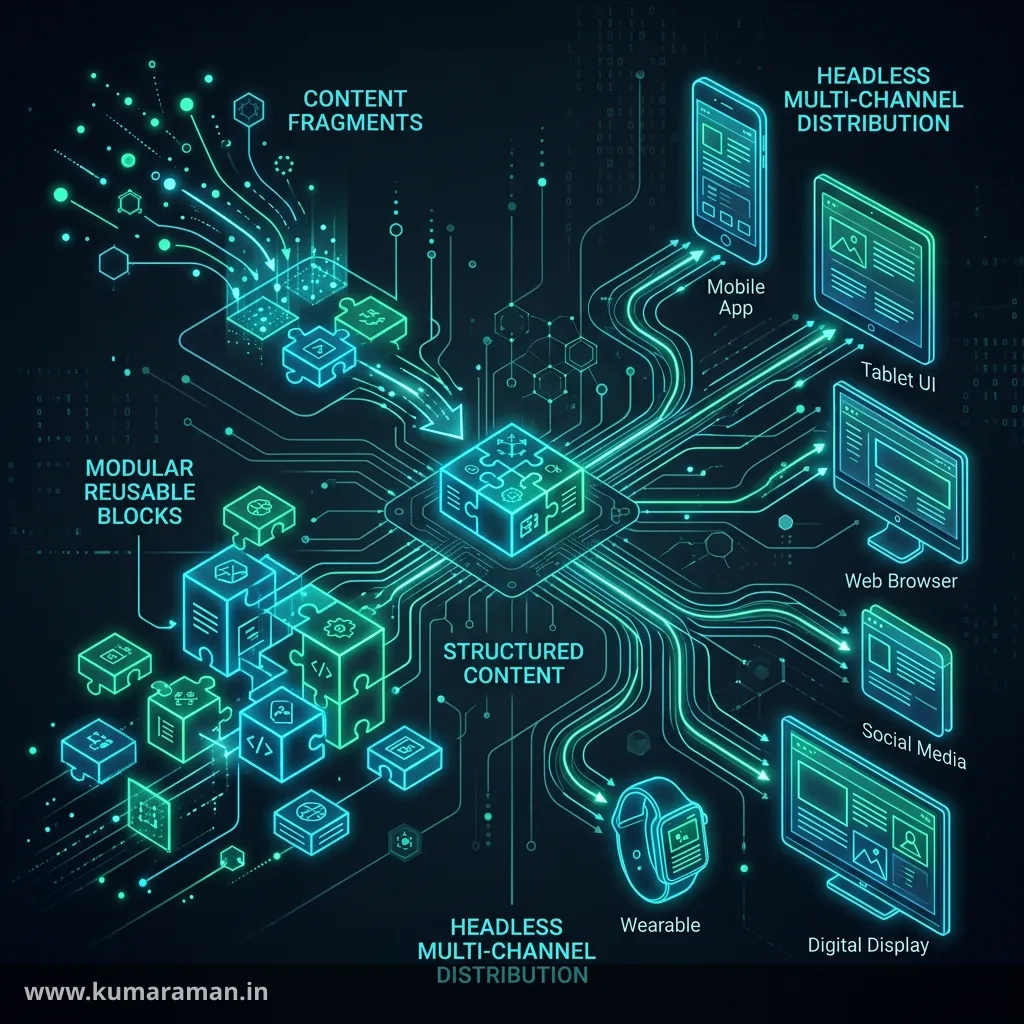
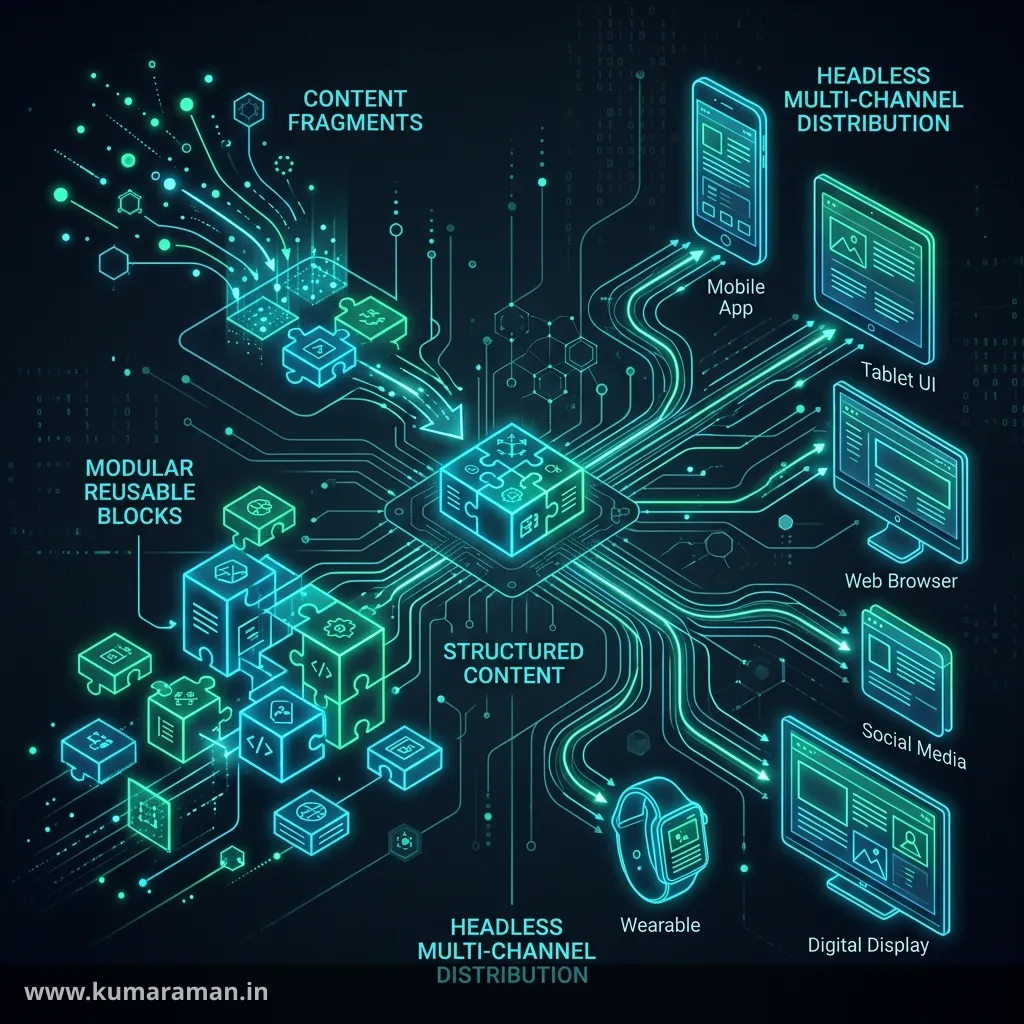
AEM has two features with almost the same name that solve almost opposite problems. Content Fragments are structured, presentation-free content — a product, an author bio, an FAQ entry — that you model once and deliver anywhere, as HTML on a page or as JSON to an app. Experience Fragments are the reverse: fully laid-out groups of components — a header, a promo banner, a footer — that you design once and reuse across many pages and channels. Mixing them up is one of the most common modeling mistakes on AEM projects, and it's expensive to undo once hundreds of authors have built content on the wrong one.
This guide covers both: Content Fragment models, variations, JCR storage, page rendering, and headless delivery (GraphQL persisted queries and the newer OpenAPI-based APIs); then Experience Fragment variations, templates, the plain-HTML rendition, Adobe Target export, and localization. Caching and permissions — where most production bugs live — get their own sections, and I call out where AEM as a Cloud Service and AEM 6.5 / 6.5 LTS differ.
It builds on the Assets guide (fragments are DAM assets), the APIs and Integrations guide (GraphQL basics), and the Dispatcher guide (cache invalidation). For localized fragments, pair it with the MSM, Live Copy & Translation guide.
Content Fragments vs Experience Fragments
The shortest correct definition: a Content Fragment is data, an Experience Fragment is a page section.
| Content Fragment (CF) | Experience Fragment (XF) | |
|---|---|---|
| What it holds | Structured fields (text, numbers, dates, references) | Components with content and layout |
| Defined by | A Content Fragment Model in /conf | An editable template (XF template) |
| Stored under | /content/dam/... (it's a dam:Asset) | /content/experience-fragments/... (it's a page) |
| Edited in | Content Fragment editor | Page editor (it's a page) |
| Delivered as | JSON (GraphQL, OpenAPI), or HTML via a component | HTML (in-page, .plain.html), Target offers, JSON |
| Variations mean | Alternate copy for the same fields | Alternate layouts/content for different channels or contexts |
| Typical uses | Articles, products, people, FAQs | Headers, footers, promos, Target offers |
My rule of thumb:
- If one piece of content needs many presentations (page, app, kiosk), model it as a Content Fragment.
- If one presentation needs to appear in many places (the same header on 4,000 pages), build it as an Experience Fragment.
Important: Don't use Experience Fragments for content that appears on only one page — Adobe's guidance says so, and it adds a layer to author and cache. And don't smuggle layout into Content Fragment rich text — it defeats presentation-neutral content.
They also compose: an XF can contain a Content Fragment component.
Content Fragment Models
Every Content Fragment is an instance of a Content Fragment Model — the schema for its fields, types, and validation. AEM also generates the GraphQL schema from models, so a model is a contract with every consumer.
Enabling models
On a new site, first create a configuration and enable the features you need:
- Tools → General → Configuration Browser → create (or edit) a configuration, e.g.
/conf/mysite, and tick Content Fragment Models (required) and GraphQL Persisted Queries (if you'll use GraphQL). - Open the Properties of your DAM folder (e.g.
/content/dam/mysite) → Cloud Services tab → select that configuration. - Optionally, on the folder's Policies tab, restrict which models are allowed there — by path or by tag. Policies are inherited by child folders unless you break inheritance.
On Cloud Service you manage models from the Content Fragments console (choose Content Fragment Models) or from Tools → General → Content Fragment Models. On 6.5 / 6.5 LTS it's the latter.
Tip: Models created in a sub-configuration can't be moved or copied to another one, and GraphQL endpoints and persisted queries stay tied to the parent configuration. Settle your
/confstructure first.
Data types
These are the data types available in the model editor on AEM as a Cloud Service:
| Data type | Use it for | GraphQL type |
|---|---|---|
| Single line text | Titles, slugs, short labels (max length configurable) | String / [String] |
| Multi line text | Body copy — Rich Text, Plain Text, or Markdown | Object with html, plaintext, markdown, json |
| Number | Prices, ratings, counts | Float / [Float] |
| Boolean | Flags | Boolean |
| Date and time | Publish dates, event times (date, time, or both) | Calendar |
| Enumeration | Fixed choices as checkbox, radio, or dropdown | String |
| Tags | AEM tags | [String] |
| Content Reference | A path to any other content — images, documents, pages | String or typed refs such as ImageRef |
| Fragment Reference | Another Content Fragment (nesting) | The referenced model's type |
| JSON Object | Free-form JSON with syntax highlighting | JSON value |
| Tab placeholder | Groups following fields into tabs in the editor | — (UI only) |
Every field has common properties: Field Label, Property Name (alphanumerics and underscores only — this becomes the GraphQL field name), Required, Render As (single value or multifield), Translatable, and Unique, which enforces the value is unique across fragments. Type-specific validation adds regex patterns for single-line text, min/max for numbers, file size and image dimension limits for content references, and min/max item counts for multifields.
Note: A Tab placeholder must sit above the fields it groups. Tabs are an editing aid — use them to keep long models authorable.
Fragment references and nesting
The Fragment Reference type is what turns flat fragments into a content graph. An Article references an Author; a Product references a list of Feature fragments. Its key properties:
- Model Type — which models the referenced fragments must be based on (you can allow several).
- Root Path — where the picker starts browsing.
- Allow Fragment Creation — lets authors create the referenced fragment inline.
- Render As — a single reference or a multifield of references.
Two built-in guards are worth knowing. AEM prevents a fragment from referencing itself, and if two fragments reference each other and you write a deep GraphQL query across them, the recursive part returns null. Model hierarchies, not cycles.
Tip: Every nesting level adds work at query time. Keep nesting shallow and flatten anything that's always read together.
What a model looks like in the repository
A model is a cq:Template under /conf/<config>/settings/dam/cfm/models/<name>. The fields live in a dialog-like structure under jcr:content/model/cq:dialog/content/items. Here's a trimmed extract modeled on Adobe's WKND Shared project — note the metaType, valueType, and the regex validation on the slug:
<jcr:root xmlns:sling="http://sling.apache.org/jcr/sling/1.0"
    xmlns:granite="http://www.adobe.com/jcr/granite/1.0"
    xmlns:cq="http://www.day.com/jcr/cq/1.0"
    xmlns:jcr="http://www.jcp.org/jcr/1.0"
    jcr:primaryType="cq:Template">
    <jcr:content
        cq:templateType="/libs/settings/dam/cfm/model-types/fragment"
        jcr:primaryType="cq:PageContent"
        jcr:title="Article"
        sling:resourceType="dam/cfm/models/console/components/data/entity/default">
        <model jcr:primaryType="cq:PageContent"
            sling:resourceType="wcm/scaffolding/components/scaffolding">
            <cq:dialog jcr:primaryType="nt:unstructured"
                sling:resourceType="cq/gui/components/authoring/dialog">
                <content jcr:primaryType="nt:unstructured"
                    sling:resourceType="granite/ui/components/coral/foundation/fixedcolumns">
                    <items jcr:primaryType="nt:unstructured">
                        <slug jcr:primaryType="nt:unstructured"
                            sling:resourceType="granite/ui/components/coral/foundation/form/textfield"
                            fieldLabel="Slug"
                            metaType="text-single"
                            name="slug"
                            required="on"
                            unique="true"
                            validation="cfm.validation.custom"
                            valueType="string">
                            <granite:data jcr:primaryType="nt:unstructured"
                                validationRegex="^[a-z0-9\\-_]{5,40}$"/>
                        </slug>
                        <authorFragment jcr:primaryType="nt:unstructured"
                            sling:resourceType="dam/cfm/models/editor/components/fragmentreference"
                            fieldLabel="Author"
                            fragmentmodelreference="/conf/mysite/settings/dam/cfm/models/author"
                            metaType="fragment-reference"
                            name="authorFragment"
                            valueType="string/content-fragment"/>
                    </items>
                </content>
            </cq:dialog>
        </model>
    </jcr:content>
</jcr:root>
You rarely hand-write this — build the model in the UI and sync it into ui.content, or scaffold it with my Content Fragment Model generator, which produces the .content.xml plus a sample GraphQL query. If you're integrating with a system that thinks in JSON Schema, the CF ↔ JSON Schema converter maps between the two.
Model lifecycle: draft, enabled, published, locked
- Draft / Enabled / Disabled — only enabled models can be used for new fragments. Disabling one keeps existing fragments (and their GraphQL types) working.
- Published — a model must be published before (or with) any fragment that uses it, or GraphQL on publish has no schema for it.
- Locked — on Cloud Service, a published model becomes read-only. You explicitly Unlock it to edit, then republish.
Important: Changing a model that already has fragments is a breaking change. Renaming a property name leaves the old values orphaned in every existing fragment and removes the old field from GraphQL. Add new fields freely; rename or delete only with a migration plan.
Authoring: the new editor vs the original editor
On AEM as a Cloud Service, fragments are primarily managed in the Content Fragments console, and the new Content Fragment editor opens from there. It's built for headless authoring and adds features the original editor lacks: a structure tree of the fragment and its references, parent references, version compare and restore, preview (in an external app or via an HTML template), and AI-assisted Generate Variations. The original editor (opened from the Assets console) still exists; the new editor even has a toggle to switch to it — but Adobe advises against having both open on the same fragment at the same time.
On AEM 6.5 and 6.5 LTS, fragments are managed from the Assets console and edited in the Assets-based editor, which supports nested fragments but not the Cloud-only console features above. On Cloud Service, if another user has checked out a fragment, the editor gives you read-only access.
Variations and "Main"
Every fragment starts with one variation — called Main in the Cloud Service UI (older UIs and the repository call it master). You can add named variations: a shorter "mobile" copy, a "social" teaser, a seasonal version. Variations share the model: they hold alternate values for the same fields.
Two behaviours surprise people:
- Sync goes one way. You can synchronize content from Main into a variation, but there's no option to push a variation's changes back into Main.
- GraphQL falls back to Main. Ask for
variation: "summer"on a fragment that doesn't have it, and you get Main. If you want only fragments that actually have that variation, filter on_variation(shown below).
How fragments are stored in the JCR
A Content Fragment is a dam:Asset with a flag and a data subtree. Knowing this layout is essential for queries, migrations, and debugging:
/content/dam/mysite/en/articles/hello-world         (dam:Asset)
└── jcr:content                                      (dam:AssetContent)
    ├── contentFragment = true                       ← marks it as a CF
    ├── metadata                                     ← dc:title, tags, etc.
    └── data
        ├── cq:model = /conf/mysite/settings/dam/cfm/models/article
        ├── master                                   ← Main variation
        │   ├── title = "Hello World"
        │   ├── slug = "hello-world"
        │   └── authorFragment = "/content/dam/mysite/en/authors/jane"
        └── summer                                   ← a named variation
            └── title = "Hello Summer"
That means a Query Builder query for "all article fragments under a folder" looks like this:
type=dam:Asset
path=/content/dam/mysite/en
boolproperty=jcr:content/contentFragment
boolproperty.value=true
property=jcr:content/data/cq:model
property.value=/conf/mysite/settings/dam/cfm/models/article
p.limit=20
(See the Query Builder reference for predicates and the JCR & Oak guide for indexing.)
Important: Don't write fragment data by setting JCR properties directly. Use the Content Fragment Java API (or the management API) so metadata, variations, and modification dates stay consistent. The Java API also does not auto-save — you must
commit()the resource resolver yourself.
Rendering Content Fragments on pages
The Core Components Content Fragment component
For "traditional" page rendering, proxy the Core Components Content Fragment component (core/wcm/components/contentfragment/v1/contentfragment). Authors pick a fragment and, optionally, a variation and a subset of elements. The dialog writes these properties:
| Property | Meaning |
|---|---|
fragmentPath | Path of the fragment to render |
variationName | Variation to use (Main if absent) |
elementNames | Which elements to render, in order (all if absent) |
paragraphScope / paragraphRange / paragraphHeadings | Render only some paragraphs of a multi-line element |
id | HTML id attribute |
Out of the box it renders elements as a description list — fine for prose, rarely what a design system wants. There's also a Content Fragment List component (core/wcm/components/contentfragmentlist/v2/contentfragmentlist) that lists fragments of a model under a parent path, filtered by tag and sorted by an element. (More on proxying and styling in the Core Components & Style System guide.)
A custom Sling Model
For real markup — a product card, a speaker profile — write your own component and adapt the Resource to com.adobe.cq.dam.cfm.ContentFragment:
package com.mysite.core.models;

import com.adobe.cq.dam.cfm.ContentElement;
import com.adobe.cq.dam.cfm.ContentFragment;
import com.adobe.cq.dam.cfm.ContentVariation;
import com.adobe.cq.dam.cfm.FragmentData;
import org.apache.commons.lang3.StringUtils;
import org.apache.sling.api.SlingHttpServletRequest;
import org.apache.sling.api.resource.Resource;
import org.apache.sling.api.resource.ResourceResolver;
import org.apache.sling.models.annotations.DefaultInjectionStrategy;
import org.apache.sling.models.annotations.Model;
import org.apache.sling.models.annotations.injectorspecific.SlingObject;
import org.apache.sling.models.annotations.injectorspecific.ValueMapValue;

import javax.annotation.PostConstruct;
import java.util.Calendar;

@Model(adaptables = SlingHttpServletRequest.class,
       defaultInjectionStrategy = DefaultInjectionStrategy.OPTIONAL)
public class ArticleCard {

    @ValueMapValue
    private String fragmentPath;

    @ValueMapValue
    private String variationName;

    @SlingObject
    private ResourceResolver resolver;

    private ContentFragment fragment;

    @PostConstruct
    protected void init() {
        if (StringUtils.isNotBlank(fragmentPath)) {
            Resource res = resolver.getResource(fragmentPath);
            fragment = res != null ? res.adaptTo(ContentFragment.class) : null;
        }
    }

    public boolean isEmpty() {
        return fragment == null;
    }

    /** Text value, honouring the selected variation and falling back to Main. */
    public String getTitle() {
        return text("title");
    }

    public Calendar getPublishDate() {
        if (fragment == null || !fragment.hasElement("publishDate")) return null;
        FragmentData data = fragment.getElement("publishDate").getValue();
        return data != null ? data.getValue(Calendar.class) : null;
    }

    private String text(String elementName) {
        if (fragment == null || !fragment.hasElement(elementName)) return null;
        ContentElement element = fragment.getElement(elementName);
        if (StringUtils.isNotBlank(variationName)) {
            ContentVariation variation = element.getVariation(variationName);
            if (variation != null) return variation.getContent();
        }
        return element.getContent();
    }
}<article data-sly-use.card="com.mysite.core.models.ArticleCard"
data-sly-test="${!card.empty}" class="article-card">
<h3 class="article-card__title">${card.title}</h3>
<time data-sly-test="${card.publishDate}">${'yyyy-MM-dd' @ format=card.publishDate}</time>
</article>ContentElement.getContent() returns the value as a string (good for text), while getValue() returns a FragmentData you convert with getValue(Class) — use that for dates, numbers, booleans, and multi-valued fields. For tests, see the JUnit & AEM Mocks guide.
Headless delivery
This is where the API landscape has changed most. On AEM as a Cloud Service there are three families:
| API | Purpose | Tier | Caching |
|---|---|---|---|
| GraphQL API (persisted queries) | Delivery, shaped by the client's query | Publish / Preview (and Author) | Cacheable via persisted queries (GET) |
| Content Fragment Delivery with OpenAPI | Delivery as plain REST JSON | Publish / Preview | CDN-cached with active invalidation |
| Sites API — Content Fragments and Models management OpenAPI | Create, read, update, delete fragments and models | Author (disabled on Publish by default) | Not for delivery |
The older Assets HTTP API content fragment support (/api/assets/...) is deprecated on Cloud Service — Adobe's guidance is to migrate existing usage to the management OpenAPI (for writes) and the Delivery OpenAPI (for reads). On 6.5 / 6.5 LTS, the OpenAPI-based APIs aren't available; your options are GraphQL (install the Content Fragments with GraphQL index package the release notes call for), the Assets HTTP API, or your own Sling Model exporter.
GraphQL and persisted queries
AEM generates a GraphQL schema from each enabled model. For a model named article you get articleByPath, articleList (offset/limit), and articlePaginated (cursor-based, first defaults to 50, max 100). Every type also exposes helper fields: _path, _id, _variation, _metadata, _model, and _references. The endpoint lives at /content/cq:graphql/<config>/endpoint.json (the global one is /content/cq:graphql/global/endpoint.json), and you explore it with the GraphiQL IDE under Tools → General.
A realistic query — note the multi-line text subfields, the nested author reference, the image reference, and the variation filter that disables fallback to Main:
query ArticlesBySlug($slug: String!, $variation: String!) {
  articleList(
    variation: $variation
    filter: {
      slug: { _expressions: [{ value: $slug }] }
      _variation: { _expressions: [{ value: $variation }] }
    }
  ) {
    items {
      _path
      _variation
      title
      body { html plaintext }
      featuredImage {
        ... on ImageRef { _path _dynamicUrl width height }
      }
      authorFragment { firstName lastName }
    }
  }
}
In production, don't let clients POST arbitrary queries. Save the query server-side as a persisted query, and clients call it with a cacheable GET:
# Persist (author) — stored under /conf/mysite/settings/graphql/persistentQueries
curl -u admin:admin -X PUT \
  -H "Content-Type: application/json" \
  "http://localhost:4502/graphql/persist.json/mysite/articles-by-slug" \
  --data '{
    "query": "query ArticlesBySlug($slug: String!) { articleList(filter: {slug: {_expressions: [{value: $slug}]}}) { items { _path title } } }",
    "cache-control": { "max-age": 300 },
    "surrogate-control": { "max-age": 600, "stale-while-revalidate": 1000 }
  }'

# Execute (publish) — variables are appended with semicolons
curl "https://publish-p123-e456.adobeaemcloud.com/graphql/execute.json/mysite/articles-by-slug;slug=hello-world"
Things to remember about persisted queries:
- Variables go after the query path as
;name=value. URL-encode special characters (%3Bfor;,%3Dfor=,%2Ffor/). - Default cache headers on Cloud Service are
max-age=60for browsers,s-maxage=7200on publish (60 on author) for the CDN, plusstale-while-revalidateandstale-if-errorof 86400. Override them per query (cache-control/surrogate-controlin the definition, as above), in the persisted query service OSGi configuration on publish, or with Cloud Manager environment variables such asgraphqlCacheControlandgraphqlSurrogateControl. - Promote them like content. Persisted queries live in
/conf/<config>/settings/graphql/persistentQueries— publish them from the GraphiQL IDE, or package that path and deploy it. - On the Dispatcher, define
CACHE_GRAPHQL_PERSISTED_QUERIESinglobal.varsto cache them; AEM's rewrite then appends.jsonso the Dispatcher can store the response. With that enabled, parameter values containing/or\are double-encoded unlessDispatcherNoCanonURLis set — worth knowing before you pass paths as variables.
Tip: Image fields can return web-optimized renditions directly. Pass
_assetTransform(format, size, crop, quality) on the list query and read_dynamicUrlfromImageRef— a relative URL you prefix with the publish host. That keeps image sizing out of your front-end code.
Content Fragment Delivery with OpenAPI
If your consumers want REST, not GraphQL, Cloud Service offers Content Fragment Delivery with OpenAPI: plain JSON by fragment ID or path, with references optionally hydrated. It's served from /adobe/contentFragments on the Publish and Preview tiers:
# List fragments under a folder (max 50 per page; follow the cursor)
curl "https://publish-p123-e456.adobeaemcloud.com/adobe/contentFragments?path=/content/dam/mysite/en/articles&limit=20"

# One fragment by path, with its direct references fully hydrated
curl "https://publish-p123-e456.adobeaemcloud.com/adobe/contentFragments/byPath?path=/content/dam/mysite/en/articles/hello-world&references=direct-hydrated"
Other endpoints return a fragment by ID (/adobe/contentFragments/{fragmentId}), its variations, its references and "referenced by" list, and models — including a model's JSON Schema (/adobe/contentFragments/models/{modelId}/jsonSchema), which pairs nicely with the CF ↔ JSON Schema converter. The references parameter accepts none, direct, direct-hydrated, all, and all-hydrated.
Operationally: it's enabled via an Adobe Support request; Publish needs no authentication (Preview does, if you opt in); responses are CDN-cached (max-age=300, s-maxage=3600) with active invalidation on publish; and the rate limit is 200 requests per second per environment (429 with Retry-After beyond that).
The management OpenAPI (writes)
For imports, migrations, and integrations that create or update fragments, use the Sites API on Author (https://author-pXXX-eYYY.adobeaemcloud.com/adobe/sites). Fragments live under /adobe/sites/cf/fragments and models under /adobe/sites/cf/models, alongside variations, versions, references, tags, translations, and a batch endpoint. Every call needs an IMS bearer token — set up an OAuth credential (Server-to-Server for back-end jobs) in the Adobe Developer Console and register the client ID with your environment through an api.yaml in the Cloud Manager config pipeline.
# Read a fragment (returns an ETag)
curl -H "Authorization: Bearer $TOKEN" \
  "https://author-p123-e456.adobeaemcloud.com/adobe/sites/cf/fragments/$FRAGMENT_ID"
Updates are JSON Patch (application/json-patch+json) and require an If-Match header with the ETag you read — the API uses optimistic locking and returns 412 on a conflict, so your integration must re-read and retry rather than blindly overwrite. The APIs and Integrations guide covers the OAuth plumbing in more depth.
Important: Keep management APIs off Publish. Adobe disables the management OpenAPI on Publish by default for good reason — delivery belongs on the cacheable delivery APIs.
Experience Fragments
An Experience Fragment is a page of type cq/experience-fragments/components/xfpage under /content/experience-fragments, authored in the regular page editor and referenced from other pages — the natural home for global chrome and reusable marketing blocks.
Structure and variations
Each XF has a Master variation (the root) and any number of additional variations — a "web" version, a compact version for a sidebar, a version for email or a third-party channel. A variation can also be created as a live copy of another, so a change to the source rolls out to the copies:
/content/experience-fragments/mysite/us/en/site/header     (the XF)
├── master                                                 (Master variation)
└── compact                                                (another variation)
Building blocks
Inside the XF editor, select components and choose Convert to building block. The block appears in the side panel and can be dragged into any fragment's layout container — handy for a CTA pattern marketers keep rebuilding, but not a replacement for proper components.
XF templates
Experience Fragments use editable templates only, and pages that include XFs must be on editable templates too. For a template to show up in the Create Experience Fragment wizard, either:
- its root resource type inherits from
cq/experience-fragments/components/xfpageand its name begins withexperience-fragment(the defaultcq:allowedTemplatespattern on/content/experience-fragmentsis/conf/(.*)/settings/wcm/templates/experience-fragment(.*)?), or - you add it to the allowed templates in the XF folder's properties in the Experience Fragments console.
Components used in an XF are allowed through the template's content policy, just like any page.
Using XFs on pages
Proxy the Core Components Experience Fragment component (core/wcm/components/experiencefragment/v2/experiencefragment). It stores one property — fragmentVariationPath — and renders that variation's content into the page. Its standout feature is localization: if the component is placed in a template (typically header and footer) and your XF tree under /content/experience-fragments mirrors your site tree under /content, the component automatically renders the fragment matching the current page's language, blueprint, or live copy. One template, one component, every locale gets its own header.
Note: The rendered markup may contain
xf-prefixed CSS classes (likexf-content-height). The Core Components docs call these private — don't style against them.
The plain-HTML rendition
Add the .plain. selector to any variation — /content/experience-fragments/mysite/us/en/site/header/master.plain.html — and you get the fragment's HTML without the page wrapper, for third-party apps or other front ends to embed. The rendition is produced by a Sling Rewriter pipeline at /libs/experience-fragments/config/rewriter/experiencefragments, which:
- makes
src,href, andactionattributes (and any-src/-hrefattributes) absolute, always pointing at the publish host via the Externalizer; - keeps only allowed tags (a default list of common text, link, image, and structural tags, configurable via
allowedTags); - optionally keeps only CSS classes matching an
allowedCssClassesregex.
Customize these by overlaying that rewriter config, and configure the Externalizer on every environment, or consumers get links to the wrong host.
Exporting to Adobe Target
With a valid Adobe Target configuration (IMS-authenticated) applied to the XF folder and the Externalizer configured, authors can use Export to Adobe Target from the XF console to push a variation to Target as an HTML offer (the default) or a JSON offer. Target then uses it in activities without anyone copying markup.
For HTML offers, AEM requests the fragment with the .nocloudconfigs.html selector, replaces html/head/body with divs (dropping meta, noscript, and title), and runs internal links through the Externalizer's publishLink(). That means everything the offer references must be published. If your publish links depend on Sling mappings, Dispatcher redirects, or sling:alias, implement com.adobe.cq.xf.ExperienceFragmentLinkRewriterProvider:
package com.mysite.core.xf;

import com.adobe.cq.xf.ExperienceFragmentLinkRewriterProvider;
import com.adobe.cq.xf.ExperienceFragmentVariation;
import org.osgi.service.component.annotations.Component;

@Component(service = ExperienceFragmentLinkRewriterProvider.class)
public class CdnLinkRewriter implements ExperienceFragmentLinkRewriterProvider {

    private static final String CDN_HOST = "https://www.mysite.com";

    @Override
    public boolean shouldRewrite(ExperienceFragmentVariation variation) {
        return variation.getPath().startsWith("/content/experience-fragments/mysite/");
    }

    @Override
    public String rewriteLink(String link, String tag, String attribute) {
        if (link == null || !link.startsWith("/")) {
            return null; // null = leave the link unchanged
        }
        String path = link.replaceFirst("^/content/mysite", "");
        return CDN_HOST + path;
    }

    @Override
    public int getPriority() {
        return 10; // highest priority wins when several providers match
    }
}
shouldRewrite decides whether this provider handles a variation, rewriteLink is called per internal link (return null to leave it as-is), and among matching providers the highest getPriority() wins. It only affects Target export links, not page rendering. (Adobe's example uses the Externalizer; the host prefix here is illustrative.) See the Analytics, Target & Data Layer guide for the Target side.
Localization and MSM for XFs
XFs participate fully in MSM and translation. The pattern that scales:
/content/experience-fragments/mysite/
├── language-masters/en/site/header/master    ← blueprint source
├── language-masters/de/site/header/master    ← translated language copy
├── us/en/site/header/master                  ← live copy of en
└── de/de/site/header/master                  ← live copy of de
Mirror your site's structure, translate language masters, and roll out live copies of the XF tree alongside the site's. With the Core XF component in templates, each locale's pages pick up their own header and footer. The MSM guide covers rollout configs.
Content Fragments localize differently: translation creates separate fragments under language roots in the DAM (/content/dam/mysite/en/..., /content/dam/mysite/de/...), and only fields marked Translatable in the model are sent for translation.
Caching considerations
When a Core XF or Content Fragment component renders on a page, the fragment's HTML is baked into the page's cached HTML — and publishing the fragment doesn't republish the page.
On 6.5 / AMS with Dispatcher flush agents, invalidation is driven by .stat files and statfileslevel. With statfileslevel set to 2 or more, activating /content/experience-fragments/mysite/... touches .stat files under /content/experience-fragments, but pages under /content/mysite check /content/mysite/.stat — which wasn't touched. So every page embedding the header keeps the old one. The same applies to Content Fragments under /content/dam. Options:
- lower
statfileslevelso the shared ancestor is invalidated (at the cost of broader invalidation); - add targeted flushing, e.g. a custom flush or ACS AEM Commons Dispatcher Flush Rules mapping fragment paths to site paths;
- rely on a short TTL for pages that embed fast-changing fragments.
On Cloud Service, the CDN caches pages by their Cache-Control TTLs, so a fragment change shows up once the embedding page's TTL expires — keep page TTLs modest if global XFs change often (see the Dispatcher guide).
For headless, GraphQL persisted queries are cached per the headers you set, so choose TTLs that match how fast content must appear; the Delivery OpenAPI gets active CDN invalidation on publish. Either way, publish models and referenced fragments before the parent.
Tip: When a fragment "didn't update," check: is the fragment (with its model and references) published? Is the embedding page still cached? Is the
.statlevel right? The Performance & Troubleshooting guide has the full flow.
Permissions
Both fragment types are ordinary repository content, so standard ACLs apply (see the Security, Users, Groups & ACLs guide):
- Models: editors need read on
/confand write/replicate on/conf/<config>/settings/dam/cfm. Keep this to a small group — a model change hits every fragment and consumer. - Content Fragments inherit ACLs from their DAM folders. Grant per folder, and use folder Policies to limit which models authors can use.
- Experience Fragments inherit ACLs from
/content/experience-fragments/.... Keep global XFs (header, footer) to a narrow group — one bad edit is a site-wide incident. - Headless on Publish is anonymous by default: anything published under a folder is readable via GraphQL. To restrict, apply Closed User Groups (CUGs) on the DAM folders and send authenticated requests; responses then include what those credentials can read plus anonymous content.
- Integrations should use dedicated technical accounts (OAuth Server-to-Server on Cloud Service), never a named author's credentials.
Cheat sheet
| Need | Where / what |
|---|---|
| Enable CF models / persisted queries | Tools → General → Configuration Browser, then folder Properties → Cloud Services |
| Restrict models per folder | Folder Properties → Policies (by path or tag) |
| Model location | /conf/<config>/settings/dam/cfm/models/<model> (cq:Template) |
| Fragment location | /content/dam/... — jcr:content/contentFragment=true |
| Model reference on a fragment | jcr:content/data/cq:model |
| Java entry point | resource.adaptTo(ContentFragment.class) |
| Render a CF on a page | core/wcm/components/contentfragment/v1/contentfragment (fragmentPath) |
| List CFs on a page | core/wcm/components/contentfragmentlist/v2/contentfragmentlist |
| GraphQL endpoint | /content/cq:graphql/<config>/endpoint.json |
| Persist a query | PUT /graphql/persist.json/<config>/<name> |
| Run a persisted query | GET /graphql/execute.json/<config>/<name>;var=value |
| Persisted queries stored in | /conf/<config>/settings/graphql/persistentQueries |
| REST delivery (Cloud) | /adobe/contentFragments, /adobe/contentFragments/byPath?path=... |
| CRUD management (Cloud, Author) | /adobe/sites/cf/fragments, /adobe/sites/cf/models (Bearer + If-Match) |
| Legacy REST | Assets HTTP API /api/assets/... (deprecated for CFs on Cloud) |
| XF location | /content/experience-fragments/... |
| XF resource type | cq/experience-fragments/components/xfpage |
| Render an XF | core/wcm/components/experiencefragment/v2/experiencefragment (fragmentVariationPath) |
| XF template naming | Name starts with experience-fragment, or add to allowed templates |
| Plain HTML | <variation>.plain.html |
| Custom Target link rewriting | ExperienceFragmentLinkRewriterProvider |
Best practices
- ✅ Model content, not pages. Name fields for meaning (
summary,heroImage), not placement (leftColumnText). - ✅ Treat models as an API contract: version them in
ui.content, add fields freely, rename or delete only with a migration. - ✅ Keep fragment nesting shallow and never design cycles.
- ✅ Use persisted queries in production, with explicit cache headers per query.
- ✅ On Cloud Service, prefer Content Fragment Delivery with OpenAPI for REST consumers and the Sites management API for writes; migrate off Assets HTTP API usage.
- ✅ Publish models first, then referenced fragments, then parents.
- ✅ Put header and footer XFs in templates with the Core XF component and mirror the site structure for automatic localization.
- ✅ Plan cache invalidation for pages that embed fragments before go-live.
Do's and Don'ts
Do
- ✅ Use a Content Fragment when the same content needs multiple presentations or headless delivery.
- ✅ Use an Experience Fragment when the same designed block appears on many pages or goes to Target.
- ✅ Read fragments through the
com.adobe.cq.dam.cfmAPI andcommit()any writes. - ✅ Use
If-Matchwith the ETag on every management API update. - ✅ Use CUGs on DAM folders when headless content must not be public.
Don't
- ❌ Don't put layout, inline styles, or component markup in Content Fragment rich text.
- ❌ Don't build an Experience Fragment for content used on a single page.
- ❌ Don't let production clients POST ad-hoc GraphQL queries — persist them.
- ❌ Don't rename model properties that already have content without a migration.
- ❌ Don't style against the private
xf-CSS classes. - ❌ Don't assume publishing a fragment refreshes the pages that embed it.
- ❌ Don't enable the management OpenAPI on Publish for delivery.
Wrapping up
Content Fragments and Experience Fragments are both about reuse, along different axes. Content Fragments reuse content across presentations: model in /conf, author fragments and variations in the DAM, render with the Core component or your own Sling Model, and deliver headless via GraphQL persisted queries or — on Cloud Service — the Delivery OpenAPI, with the Sites API for writes. Experience Fragments reuse presentation: author them from XF templates, place them with the Core XF component (ideally in templates for automatic localization), and expose them as plain HTML or Target offers. Choose correctly up front, plan invalidation and permissions early, and both will scale with you.
Continue with the Assets guide for how the DAM stores and processes the assets your fragments reference, the APIs and Integrations guide for OAuth and consuming AEM from other systems, the MSM, Live Copy & Translation guide for localizing fragments, and the Dispatcher guide for getting invalidation right. And when you're ready to build, scaffold your first model with the Content Fragment Model generator.
Discussion
Loading discussion…
Try a related tool
Subscribe to the Newsletter
Get the latest articles, tutorials, and tech insights delivered straight to your inbox. No spam, unsubscribe anytime.