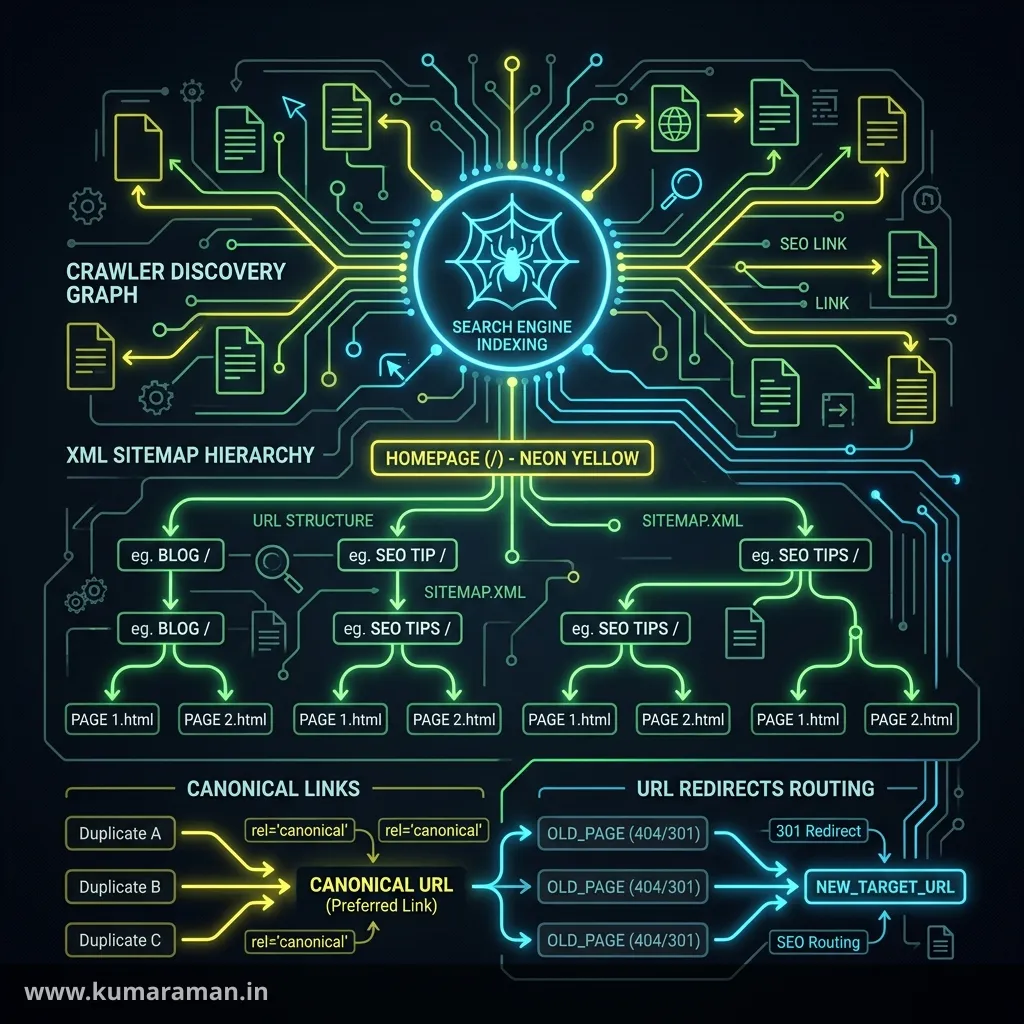
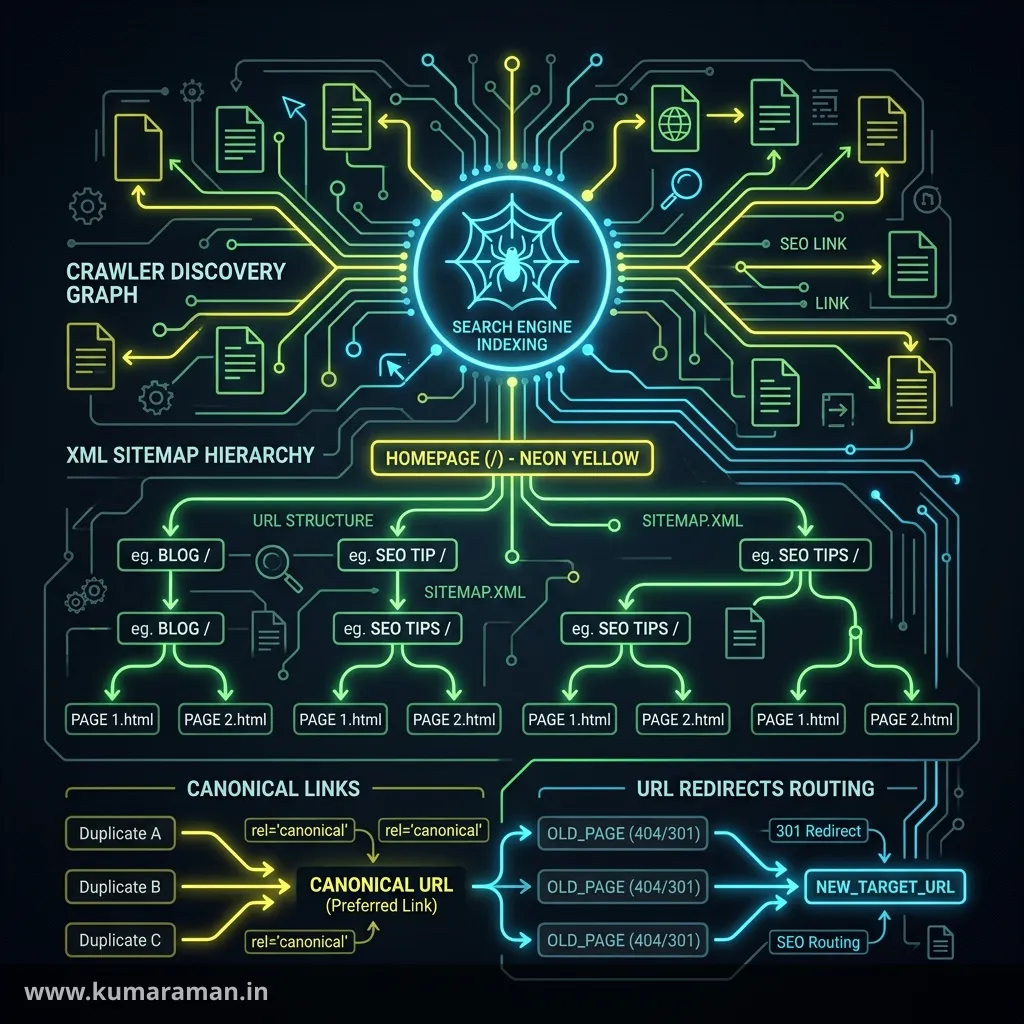
AEM gives you everything you need for solid technical SEO — but little of it is switched on by default, and it's spread across tiers that different teams own. The sitemap generator ships without a schedule. Canonical and hreflang tags depend on an Externalizer config and Sling mappings that often exist only on publish. Redirects can live at the CDN, in Apache, in the repository, or in a page property — use all four and you get redirect chains nobody can explain. SEO problems on AEM are rarely about "what should the tag say"; they're about which layer produces it and whether that layer knows the public URL.
This guide covers clean URLs, XML sitemaps with the Apache Sling Sitemap module, robots.txt, canonical and hreflang tags from the Core Components Page, vanity URLs and redirects, meta/Open Graph tags, structured data, pagination, and SPA/headless SEO — calling out where AEM as a Cloud Service (AEMaaCS) and AEM 6.5 differ. A cheat sheet, best practices, and do's & don'ts close it out.
It builds on the Dispatcher guide (rewrites, filters, caching), the Sling guide (resource resolution and mappings), and the Core Components & Style System guide. For multilingual structure, pair it with the MSM, Live Copy & Translation guide.
Where SEO lives in an AEM stack
Most AEM SEO bugs are one tier assuming another handles something, so start with ownership:
| Concern | Owned by | Typical mechanism |
|---|---|---|
| Short, clean public URLs | Publish + Dispatcher | Sling resource mapping (outgoing) + mod_rewrite (incoming) |
| Absolute URLs in tags/sitemaps | Publish | Externalizer + Sling mappings (via SitemapLinkExternalizer) |
| XML sitemaps | Publish (usually) | Apache Sling Sitemap module + AEM's page tree generator |
robots.txt, X-Robots-Tag | Dispatcher / CDN | Rewrite to a DAM file; Header set or CDN rules |
| Canonical, hreflang, robots meta | Publish (page render) | Core Components Page + SeoTags |
| Redirects | CDN, Dispatcher, or publish | cdn.yaml, RewriteMap, ACS Commons, page redirect |
| Meta, Open Graph, JSON-LD | Publish (page render) | Page properties + custom head / Sling Model |
| Cacheability of variants | Dispatcher / CDN | Selectors, /ignoreUrlParams, TTLs |
When a canonical shows the wrong host, the fix is almost never in HTL — it's the Externalizer, the mappings, or a missing X-Forwarded-Proto header.
Clean URLs: mappings in, mappings out
Everything in AEM lives under /content/<site>/..., and that's not what you want users or Google to see. Adobe's SEO and URL management best practices recommend short, lowercase, hyphenated URLs, sub-paths rather than subdomains for locales (/es/ over es.example.com), and selectors rather than query parameters for variants. Getting there takes two halves that must agree:
- Outgoing — links AEM writes into pages must be shortened (
/content/mysite/en/aboutbecomes/en/about.html). - Incoming — Apache must expand the short URL back to the full repository path before the Dispatcher module sees it.
Outgoing: Sling resource mapping
Adobe's recommended approach is the URL Mappings property (resource.resolver.mapping) of the Apache Sling Resource Resolver Factory (PID org.apache.sling.jcr.resource.internal.JcrResourceResolverFactoryImpl), deployed as a publish-only OSGi config:
{
  "resource.resolver.mapping": [
    "/content/mysite/(.*)</$1"
  ]
}
Save it as ui.config/.../osgiconfig/config.publish/org.apache.sling.jcr.resource.internal.JcrResourceResolverFactoryImpl.cfg.json. It's publish-only on purpose: authors need real paths in the editor.
Mappings only help if components use them: every rendered link must go through resourceResolver.map(request, path). Core Components' link handling does; custom code that concatenates page.getPath() + ".html" leaks /content/... URLs.
Note: Mapping config replaces the property's default value, so if you had other entries (the Sling default includes
/:/and/content/:/), decide deliberately what you keep. Test withresourceResolver.map()on publish, or try the Sling Resolver Simulator.
/etc/map and why Adobe prefers the OSGi route
The classic alternative is sling:Mapping nodes under /etc/map (the location is the resource.resolver.map.location property, default /etc/map), using sling:match, sling:internalRedirect, and sling:redirect. It's fully supported and the natural fit for host-based rules across multiple domains, but Adobe calls out a real trap: if publish resolves /my-page.html internally via /etc/map, the Dispatcher caches the response at /my-page.html. When the page is activated, the flush request targets /content/mysite/my-page, which doesn't match the cached file, so stale content stays in cache.
The fix is the same either way: do the incoming expansion in Apache so the Dispatcher always requests and caches the long path.
Incoming: Dispatcher rewrites
# conf.d/rewrites/rewrite.rules (AEMaaCS) or your vhost (AMS/on-prem)
RewriteEngine On

# Map short URLs back to the repository before mod_dispatcher runs
RewriteCond %{REQUEST_URI} !^/(content|etc\.clientlibs|libs|apps|conf|bin|system)/
RewriteCond %{REQUEST_URI} \.(html|xml)$
RewriteRule ^/(.*)$ /content/mysite/$1 [PT,L]
PT (pass-through) hands the rewritten URI to the Dispatcher module, so it's cached as /content/mysite/en/about.html and flushes work. Include xml, or your sitemap URLs won't be expanded — a common community issue. The Dispatcher Tester lets you trace a URL through filters.
Lowercase, .html, and trailing slashes
- Lowercase: train authors to create lowercase page names, and 301 uppercase requests. Adobe's pattern uses
RewriteMap lowercase int:tolower. Scope it — you don't want to lowercase DAM assets or client library paths that legitimately contain capitals:
RewriteMap lowercase int:tolower
RewriteCond %{REQUEST_URI} [A-Z]
RewriteCond %{REQUEST_URI} !^/(content/dam|etc\.clientlibs)/
RewriteRule ^(.*)$ ${lowercase:$1} [R=301,L]
Place it before your expansion rule; a [PT,L] rule earlier in the file would end processing first.
- The
.htmlextension: Sling resolves scripts by extension, and the Dispatcher only caches URLs that have one — Adobe's Dispatcher docs list "request URL is missing extension" as a non-cacheable reason. Keeping.htmlis the zero-effort, fully cacheable choice. Extensionless URLs are possible (rewrite/en/aboutto/content/mysite/en/about.htmlwithPT, and strip.htmlfrom outgoing links), but it's custom work on both sides, and every canonical, sitemap entry, and internal link must use the same form. - Trailing slashes: pick one form, and 301 the other to it.
/en/about/and/en/about.htmlare different URLs to a crawler; serving both with 200 is duplicate content.
Tip: Whatever URL shape you choose, the canonical tag, sitemap
loc, hreflanghref, and internal links must all emit exactly that shape. Consistency is the actual goal; the shape is secondary.
Localized page names with sling:alias
Renaming /es/home to /es/casa would break MSM and translation relationships, which rely on matching page names across locales. Instead, set sling:alias (the Alias field in Page Properties → Advanced) to casa. The page stays at /es/home in the repository while users see the localized name.
XML sitemaps with the Apache Sling Sitemap module
AEM generates sitemaps with the Apache Sling Sitemap module plus AEM's own page-tree generator. It's the product feature on AEMaaCS and on AEM 6.5 since 6.5.11.0 — older 6.5 installs need a custom servlet. It supersedes the ACS Commons Sitemap Generator.
How it's structured
- A resource becomes a sitemap root when it (or its
jcr:content) hassling:sitemapRoot = true. Authors set it with Generate Sitemap in Page Properties → Advanced → SEO. - The sitemap root closest to the repository root is the top-level root; it serves a sitemap index in addition to its sitemap. Roots below it are nested sitemaps that get listed in that index.
- Sitemaps are served with selectors on the top-level root's URL:
/content/mysite/en.sitemap-index.xml          → sitemap index (submit this one)
/content/mysite/en.sitemap.xml                → sitemap of the root itself
/content/mysite/en.sitemap.news-sitemap.xml   → nested root at en/news
Root placement is a design decision: mark each language root and each gets its own index; mark the site root as well and the language roots become nested sitemaps under one index.
Generators and filters
The Sling module is abstract: SitemapGenerator implementations decide what goes in. AEM Sites ships a default page-tree generator (PageTreeSitemapGenerator) that is pre-configured to output canonical URLs only, plus language alternates where they exist. Configure it via Adobe AEM SEO – Page Tree Sitemap Generator — for example enable Add Last Modified with cq:lastModified as the source (Adobe's recommendation on publish). To exclude pages, implement a SitemapPageFilter; for full control, register a custom SitemapGenerator with a higher service.ranking. Adobe's documented pattern extends Sling's ResourceTreeSitemapGenerator and reuses the default generator's isPublished/isNoIndex/isRedirect/isProtected checks:
@Component(service = SitemapGenerator.class,
           property = { "service.ranking:Integer=20" })
public class SiteSitemapGenerator extends ResourceTreeSitemapGenerator {

    @Reference private SitemapLinkExternalizer externalizer;
    @Reference private PageTreeSitemapGenerator defaultGenerator;

    @Override
    protected void addResource(@NotNull String name, @NotNull Sitemap sitemap, Resource resource)
            throws SitemapException {
        Page page = resource.adaptTo(Page.class);
        if (page == null) return;
        String location = externalizer.externalize(resource);
        Url url = sitemap.addUrl(location + ".html");
        // add lastmod, alternates, image extensions ... as needed
    }

    @Override
    protected final boolean shouldInclude(@NotNull Resource resource) {
        Page page = resource.adaptTo(Page.class);
        return super.shouldInclude(resource) && page != null
            && defaultGenerator.isPublished(page)
            && !defaultGenerator.isNoIndex(page)
            && !defaultGenerator.isRedirect(page)
            && !defaultGenerator.isProtected(page);
    }
}
The builder API also has extensions for alternate languages, images, video, and news — no hand-written XML.
Turning generation on: the scheduler
The part everyone misses: AEM ships no SitemapScheduler configuration, so background generation is effectively opt-in. Create a factory config for PID org.apache.sling.sitemap.impl.SitemapScheduler:
{
  "scheduler.name": "mysite-sitemaps",
  "scheduler.expression": "0 0 0 * * ?",
  "searchPath": "/content/mysite"
}
Save it as config.publish/org.apache.sling.sitemap.impl.SitemapScheduler~mysite.cfg.json. It also accepts names, includeGenerators, and excludeGenerators, so a news sitemap can run more often than the nightly full build. Each run queues jobs on the org/apache/sling/sitemap/build topic.
| Topic | Detail |
|---|---|
| Where files go | /var/sitemaps by default (storagePath of the Sling Sitemap Storage config) |
| Size limits | SitemapServiceConfiguration: maxEntries default 50,000, maxSize default 10 MB |
| Auto-balancing | Background generation splits into multiple files when limits are hit |
| On-demand mode | Opt-in per generator; no auto-balancing, so only for small sites |
| Which tier | Adobe recommends publish, because the Sling mappings needed for correct canonical URLs usually exist only there |
Google's limit is 50,000 URLs or 50 MB uncompressed per file, so the defaults sit inside it. Google ignores priority and changefreq and trusts lastmod only when it's consistently accurate — don't fake it.
Important: Generating on author only works if a custom
SitemapLinkExternalizercan produce public URLs there, and then you must be careful with unpublished, modified, or access-restricted content. Default to publish.
Serving sitemaps through the Dispatcher
On AEMaaCS, the immutable default_filters.any in the Dispatcher SDK already allows the sitemap selectors:
/aem0054 { /type "allow" /method "GET" /path "/content/*" /selectors 'sitemap(-index)?' /extension "xml" }On AMS/on-prem, add an equivalent rule yourself. Then expose a friendly URL and advertise it in robots.txt:
RewriteRule ^/sitemap\.xml$ /content/mysite/en.sitemap-index.xml [PT,L]Two checks. Sitemaps are generated on publish, not replicated, so make sure your /invalidate rules cover .xml or give sitemap responses a short TTL. And verify entries are absolute URLs on your real domain — relative paths or an adobeaemcloud.com host mean the Externalizer or mappings need fixing (see Canonical URLs below). The Robots & Sitemap tool checks both.
robots.txt and X-Robots-Tag
robots.txt must live at the host root. The common AEM pattern is to publish it as an asset and rewrite to it:
RewriteRule ^/robots\.txt$ /content/dam/mysite/robots.txt [PT,L]Since .txt isn't allowed from the DAM by default, add a narrow filter for exactly that path:
/0100 { /type "allow" /method "GET" /path "/content/dam/mysite/robots.txt" }Adobe advises keeping robots.txt in the repository and replicating it rather than dropping it into the docroot, where Dispatcher flushes can clear it.
For non-production AEMaaCS environments, don't rely on swapping files: the Dispatcher runtime exposes ENVIRONMENT_DEV, ENVIRONMENT_STAGE, and ENVIRONMENT_PROD defines, so one config can block indexing everywhere but production:
<IfDefine !ENVIRONMENT_PROD>
  Header always set X-Robots-Tag "noindex, nofollow"
</IfDefine>
The same header keeps PDFs and other assets out of the index, since they can't carry a meta tag.
Important: robots.txt controls crawling, not indexing. Google is explicit: for
noindexto work, the page must not be blocked by robots.txt — otherwise the crawler never sees the directive, and the URL can still appear in results via external links. UseDisallowfor crawl budget,noindexfor removal, and never both on the same URL.
Finally, add a Sitemap: line to robots.txt with your absolute sitemap index URL.
Canonical URLs
What Core Components render
The Core Components Page component (v2/v3) renders the SEO head for you. The relevant part of head.links.html is:
<link data-sly-test="${page.canonicalLink}" rel="canonical" href="${page.canonicalLink}">
<link data-sly-test="${page.alternateLanguageLinks}"
      data-sly-repeat="${page.alternateLanguageLinks.entrySet}"
      rel="alternate" hreflang="${item.key.toLanguageTag}" href="${item.value}">
and head.html renders <meta name="robots"> from page.robotsTags. Behind these sit the Page model methods getCanonicalLink(), getAlternateLanguageLinks(), and getRobotsTags() (added in version 12.22.0 of the Core Components models API), which delegate to AEM's SeoTags adapter (com.adobe.aem.wcm.seo.SeoTags). The rules the implementation enforces are worth knowing:
- Canonical comes from
SeoTags.getCanonicalUrl(), which uses the sameSitemapLinkExternalizeras the sitemap — so your sitemap and canonical are consistent by design. IfSeoTagsis unavailable, it falls back to the externalized URL of the current page. - No canonical is rendered on
noindexpages. It would conflict with the exclusion. - Authors can override the canonical with Canonical Url in Page Properties → Advanced → SEO (stored as
cq:canonicalUrl). Left blank, the page's own URL is canonical. - Robots Tags (stored as
cq:robotsTags) rendernoindex,nofollow, and friends. When options conflict, the more permissive one wins.
On AEM 6.5, SeoTags belongs to the same com.adobe.aem.wcm.seo API as the sitemap feature (6.5.11.0+). On an instance without it, the model catches the missing class: you get only the fallback canonical and no robots or hreflang output. AEMaaCS has it all.
Getting the host and protocol right: the Externalizer
Canonicals must be absolute. Google supports relative ones but warns they cause long-term problems. The absolute part comes from the Externalizer (PID com.day.cq.commons.impl.ExternalizerImpl, property externalizer.domains) combined with your Sling mappings.
On AEMaaCS, the defaults read Cloud Manager environment variables, and Adobe is strict about it:
{
  "externalizer.domains": [
    "local $[env:AEM_EXTERNALIZER_LOCAL;default=http://localhost:4502]",
    "author $[env:AEM_EXTERNALIZER_AUTHOR;default=http://localhost:4502]",
    "publish $[env:AEM_EXTERNALIZER_PUBLISH;default=http://localhost:4503]",
    "preview $[env:AEM_EXTERNALIZER_PREVIEW;default=http://localhost:4503]"
  ]
}
If you deploy your own ExternalizerImpl config, keep these four entries exactly and add yours after them (<name> https://www.example.com). Don't set AEM_EXTERNALIZER_* yourself; for a custom domain, define AEM_CDN_DOMAIN_PUBLISH / AEM_CDN_DOMAIN_PREVIEW in Cloud Manager, which AEM applies at startup. Adobe also notes the Externalizer is meant for single-domain applications — multi-domain setups rely on host-specific Sling mappings. On AEM 6.5, configure externalizer.domains per run mode as usual.
Canonicals showing http:// usually mean AEM isn't seeing X-Forwarded-Proto: https; Adobe's KB fix is to ensure the header reaches AEM and configure the Felix SSL filter (org.apache.felix.http.sslfilter.SslFilter) to trust it. Two canonical tags mean custom head code is duplicating the Core Component's — remove it.
When to override a canonical
Canonical is a hint. Google weighs redirects and rel="canonical" as strong signals and sitemap inclusion as weak. Override it for true duplicates — a print selector, a vanity URL, syndicated copies. Don't use it to collapse pagination, don't point it at another language, and never use robots.txt or noindex for canonicalization.
Hreflang and multilingual sites
Google's localized versions guide boils down to a few rules:
- Each version must list itself and every other version.
- Links must be reciprocal — if two pages don't point to each other, both annotations are ignored.
hrefvalues must be fully qualified URLs.- Codes are ISO 639-1 language, optionally with ISO 3166-1 Alpha-2 region (
en-GB). A region alone is invalid. x-defaultmarks the fallback for users whose language matches nothing — typically a language selector or global page.- Use HTML
linktags, HTTP headers, or the sitemap — any one, consistently.
What AEM gives you
The Page component renders hreflang links when the Render alternative language links option (renderAlternateLanguageLinks) is enabled in the page policy. Per the implementation, links are emitted only when the page is canonical (no custom canonical, or one pointing to itself) and not noindex. That's correct behaviour: hreflang on a non-canonical page sends conflicting signals.
The alternates come from SeoTags.getAlternateLanguages() — language copies of the page that are themselves included in sitemaps, as absolute URLs. Structure matters here: language copies are found through language roots (the Language and Language Root page properties) and matching page names beneath them. That's why a clean MSM and translation setup pays off in SEO — keep names aligned (use sling:alias for localized slugs) and hreflang works without code.
The default sitemap generator also includes language alternates, so you get hreflang in both the head and the sitemap without extra code.
Note: The Core Components map is keyed by
Locale, and the out-of-the-box output doesn't include anx-defaultentry. If you want one, add it in your page's custom head — and point it at a page that exists in every locale set, usually the global home or a language selector.
Check reciprocity with the Hreflang Validator — missing return links are the most common hreflang bug.
Vanity URLs
A vanity URL is a second, friendlier address for a page — /summer-sale for a campaign. Authors add them in Page Properties → Basic, which writes sling:vanityPath (multi-value). The Sling mechanics:
| Property | Effect |
|---|---|
sling:vanityPath | Alternative path(s) that resolve to this resource |
sling:redirect (Boolean, on a vanity resource) | true → respond with an HTTP redirect instead of rendering in place |
sling:redirectStatus | Status for that redirect; defaults to 302 |
sling:vanityOrder | Tie-breaker when two resources claim the same vanity path |
(In /etc/map, sling:redirect instead holds a target URL.) In the UI, the Redirect Vanity URL checkbox sets it.
A vanity that renders in place is a duplicate — Adobe warns it fragments ranking value and needs a canonical. Prefer redirecting vanities with sling:redirectStatus set to 301 when permanent. Adobe also requires vanity URLs to be unique, regex-free, and not an existing page's path.
Performance and Dispatcher caveats
- Sling loads vanity paths into an in-memory mapping table (backed by a bloom filter), so every vanity adds memory and startup work. The Resource Resolver Factory exposes
resource.resolver.vanitypath.maxEntries,resource.resolver.vanitypath.allowlist/denylist(restrict which paths are scanned — for example only/content/), andresource.resolver.vanitypath.cache.in.background. - The Dispatcher filter usually denies
/summer-salebecause it isn't under/content. The classic answer is the farm's/vanity_urlssection, which periodically fetches the list from/libs/granite/dispatcher/content/vanityUrls.htmland allows filter-denied URLs that appear in it (requires the vanity URL service package on publish, per Adobe's Dispatcher docs). The AEMaaCS project archetype's default farm includes this block commented out. The alternative is explicit rewrites. - A vanity rendered in place is cached under the vanity path, so it has the same stale-cache problem as
/etc/map— one more reason to redirect.
Tip: Treat vanity URLs as an authoring convenience for a handful of campaign URLs. For migrations, bulk legacy URLs, or anything a marketing team manages at scale, use a proper redirect layer.
Redirects
301 vs 302 (and chains)
Google treats 301/308 as a strong signal that the target becomes canonical, and 302/303/307 as "follow, but keep the original". Avoid meta refresh and JavaScript redirects. For site moves, Google advises keeping redirects at least a year. Googlebot follows up to 10 hops but recommends short chains (ideally no more than 3); aim for one. The Redirect Checker shows the full chain.
Choosing a layer
Adobe's URL redirect overview lays out the options:
| Layer | Tool | Best for | Watch out for |
|---|---|---|---|
| CDN (AEMaaCS) | redirects rules in cdn.yaml | Domain/host redirects, a small number of fixed rules; fastest | Config file (with traffic filter rules) capped at 100 KB; pipeline deploy |
| Apache/Dispatcher | mod_rewrite, RewriteMap | Pattern rules, http→https, lowercase, large maps | Developer-owned unless maps are pipeline-free |
| AEM publish | ACS Commons Redirect Manager | Author-managed rules with regex, 301/302 | First request hits publish; community-supported |
| AEM publish | ACS Commons Redirect Map Manager | Author-managed maps exported for RewriteMap | Community-supported |
| Page | Page redirect (Advanced → Redirect) | One page pointing elsewhere | 302 unless Permanent Redirect is checked |
The CDN rule format on AEMaaCS looks like this (status defaults to 301):
kind: "CDN"
version: "1"
data:
  redirects:
    rules:
      - name: apex-to-www
        when: { reqProperty: domain, equals: "example.com" }
        action:
          type: redirect
          location:
            reqProperty: url
            transform:
              - op: replace
                match: '^/(.*)$'
                replacement: 'https://www.example.com/\1'
Large redirect maps without pipelines (AEMaaCS)
Thousands of legacy URLs belong in an Apache RewriteMap — a hash lookup, not thousands of regexes. On AEMaaCS, pipeline-free redirects let the map live in the publish repository (a published DAM file, or output of ACS Commons Redirect Map Manager 6.7.0+ / Redirect Manager 6.10.0+) and Apache reloads it itself. Deploy src/opt-in/managed-rewrite-maps.yaml once (flexible mode):
maps:
  - name: legacy.map
    path: /content/dam/redirectmaps/legacy-redirects.txt
and reference it from your rewrite rules — the map is stored under /tmp/rewrites/ in sdbm format:
RewriteMap legacy dbm=sdbm:/tmp/rewrites/legacy.map
RewriteCond ${legacy:$1} !=""
RewriteRule ^(.*)$ ${legacy:$1|/} [L,R=301]
Apache re-reads the map every 300 seconds by default (ttl changes it; wait: true delays startup until it's loaded), and entries are limited to 1,024 characters. The format is plain source target lines:
/old-products/widget.html   /en/products/widget.html
/about-us.html              /en/about.html
On AMS/on-prem, RewriteMap works the same way, but you manage the file yourself.
Important: Redirect one hop to the final URL. If a page moves twice, update the old entry rather than chaining
A → B → C, and make sure your redirect targets already include the canonical shape (lowercase, trailing-slash policy,https,www) so the target doesn't redirect again.
Meta tags and Open Graph
The Page component renders <title> (from the page's title fields, plus an optional brand slug), meta description from jcr:description, and meta keywords from page tags. That covers basic meta.
Open Graph and Twitter Card tags are not rendered by Page v3 — the old social sharing snippets were deprecated and removed from v3. Add them in your proxy page component's customheaderlibs.html (the extension point the Core Page includes in the head):
<!-- /apps/mysite/components/page/customheaderlibs.html -->
<sly data-sly-use.og="com.mysite.core.models.OpenGraph">
  <meta property="og:type" content="website">
  <meta property="og:title" content="${og.title}">
  <meta property="og:description" data-sly-test="${og.description}" content="${og.description}">
  <meta property="og:url" content="${og.url}">
  <meta property="og:image" data-sly-test="${og.image}" content="${og.image}">
  <meta name="twitter:card" content="summary_large_image">
</sly>
Back it with a Sling Model that reads page properties, uses the featured image (cq:featuredimage) for og:image, and externalizes og:url and the image — scrapers need absolute URLs. Preview it with the Meta Tag Preview tool.
Structured data (JSON-LD)
Out of the box (Core Components 2.31.0+)
Core Components 2.31.0 added page-level structured data to all versions of the Page component: each entry in the cq:structuredData property is rendered as a script type="application/ld+json" block in the head. On AEMaaCS release 2026.6.0 and later, authors can add blocks in Page Properties → Advanced → SEO → Structured Data (JSON-LD) — each entry must be one complete JSON-LD object of a schema.org type (FAQPage, Product, and so on). On AEM 6.5, that authoring UI isn't available, so plan on the model-based approach below.
Generated from content with a Sling Model
Hand-authored JSON drifts from the page, so generate types derivable from content (Article, BreadcrumbList):
@Model(adaptables = SlingHttpServletRequest.class)
public class ArticleSchema {

    @ScriptVariable private Page currentPage;
    @OSGiService private Externalizer externalizer;
    @SlingObject private ResourceResolver resolver;

    private String json;

    @PostConstruct
    protected void init() throws JsonProcessingException {
        Map<String, Object> ld = new LinkedHashMap<>();
        ld.put("@context", "https://schema.org");
        ld.put("@type", "Article");
        ld.put("headline", currentPage.getTitle());
        ld.put("description", currentPage.getDescription());
        ld.put("mainEntityOfPage",
               externalizer.publishLink(resolver, currentPage.getPath()) + ".html");
        Calendar modified = currentPage.getLastModified();
        if (modified != null) {
            ld.put("dateModified", modified.toInstant().toString());
        }
        // Serialize with a JSON library, then neutralize "</" so content can't close the script tag
        json = new ObjectMapper().writeValueAsString(ld).replace("</", "<\\/");
    }

    public String getJson() { return json; }
}<sly data-sly-use.schema="com.mysite.core.models.ArticleSchema">
<script type="application/ld+json">${schema.json @ context='unsafe'}</script>
</sly>context='unsafe' is acceptable here only because the model builds the output with a JSON serializer and escapes </ — never concatenate strings into JSON-LD. Use externalizer.publishLink (or the same link logic as the canonical) so URLs are absolute. Draft and validate schemas with the Schema Builder. For more on Sling Models, see the Backend Development guide.
Pagination, query parameters, and Dispatcher caching
Google's pagination guidance: give each page its own URL and self-referencing canonical, don't canonicalize page 2 to page 1, don't use #fragments for page numbers, and note that rel="next"/rel="prev" are no longer used by Google.
In AEM this collides with Dispatcher caching. The Dispatcher doesn't cache URLs with query parameters unless those parameters are listed in /ignoreUrlParams — and an ignored parameter is ignored for cache lookup too, so every value serves the first cached response. That's right for tracking parameters and catastrophic for pagination:
/ignoreUrlParams {
  /0001 { /glob "*"      /type "allow" }   # ignore unknown params (tracking etc.)
  /0002 { /glob "page"   /type "deny" }    # never ignore: changes the content
  /0003 { /glob "sort"   /type "deny" }
}
Adobe recommends this allowlist style, and more broadly prefers selectors over query strings: /en/news.page-2.html is a distinct, cacheable file invalidated with its page. Validate selectors and 404 unexpected values — unbounded selectors are a cache-flooding and duplicate-content risk (see the Dispatcher guide).
For facets and sort orders, Google suggests noindex or a robots.txt disallow for unwanted variations — one or the other, not both.
Performance and Core Web Vitals
Core Web Vitals (LCP, INP, CLS) are part of Google's page experience signals. On AEM the big levers are a high Dispatcher/CDN cache-hit ratio, lean client libraries, responsive Core Image renditions, and no render-blocking custom head scripts — see the Performance & Troubleshooting guide, and the Edge Delivery Services guide for an architecture built around a 100 Lighthouse score. The Website Audit tool gives a quick combined speed and SEO check.
SPA and headless SEO
Google can render JavaScript, but rendering is deferred and can fail, and many other crawlers and social scrapers don't run JS. For SPA Editor or headless frontends:
- Render on the server so content and SEO tags are in the initial HTML — see Next.js App Router for AEM developers.
- The frontend owns SEO tags. Model SEO fields (title, description, canonical override, robots, OG image) in your Content Fragment models and render them in the app.
- Sitemaps and redirects move too. If public URLs belong to a separate app, generate the sitemap there and run redirects at the CDN or app edge.
- Real links, real status codes. Use
a hreflinks, and return real 404s and 301s from the server instead of client-side "not found" views or JavaScript redirects.
Cheat sheet
| Need | Where | Key name |
|---|---|---|
| Shorten outgoing URLs | OSGi (publish) | resource.resolver.mapping on org.apache.sling.jcr.resource.internal.JcrResourceResolverFactoryImpl |
| Host-based mappings | Repository | /etc/map (sling:match, sling:internalRedirect, sling:redirect, sling:status) |
| Expand incoming URLs | Dispatcher | RewriteRule ... /content/mysite/$1 [PT,L] |
| Localized slug | Page property | sling:alias |
| Mark sitemap root | Page property | sling:sitemapRoot = true ("Generate Sitemap") |
| Schedule sitemaps | OSGi factory | org.apache.sling.sitemap.impl.SitemapScheduler (scheduler.expression, searchPath) |
| Sitemap URLs | Publish | <root>.sitemap-index.xml, <root>.sitemap.xml |
| Sitemap storage | Repository | /var/sitemaps |
| Hide pages from sitemap | Java | SitemapPageFilter or a custom SitemapGenerator |
| Canonical override | Page property | cq:canonicalUrl |
| Robots meta | Page property | cq:robotsTags |
| hreflang links | Page policy | renderAlternateLanguageLinks |
| Absolute URLs | OSGi | com.day.cq.commons.impl.ExternalizerImpl / externalizer.domains |
| Custom domain in Externalizer (AEMaaCS) | Cloud Manager env var | AEM_CDN_DOMAIN_PUBLISH, AEM_CDN_DOMAIN_PREVIEW |
| Vanity URL | Page property | sling:vanityPath, sling:redirect, sling:redirectStatus |
| JSON-LD (authored) | Page property | cq:structuredData (Core Components 2.31.0+) |
| Edge redirects (AEMaaCS) | cdn.yaml | data.redirects.rules |
| Large redirect maps (AEMaaCS) | src/opt-in/managed-rewrite-maps.yaml | RewriteMap ... dbm=sdbm:/tmp/rewrites/<name> |
| Non-prod noindex (AEMaaCS) | Dispatcher | IfDefine !ENVIRONMENT_PROD + X-Robots-Tag |
| Cacheable query params | Dispatcher | /ignoreUrlParams (allowlist style) |
Best practices
- ✅ Decide the one public URL shape (host, protocol, lowercase, extension, trailing slash) up front and make every tier emit it.
- ✅ Shorten URLs with OSGi resource mappings on publish and expand them in Apache with
PT, so the Dispatcher caches and flushes the real path. - ✅ Enable the Sling Sitemap scheduler on publish, submit the sitemap index, and list it in robots.txt.
- ✅ Let Core Components render canonical, robots, and hreflang; turn on
renderAlternateLanguageLinksin the page policy. - ✅ Put redirects at the outermost sensible layer: CDN for host rules,
RewriteMapfor bulk, ACS Commons or pipeline-free maps when authors own them. - ✅ Generate JSON-LD from content with a Sling Model and a JSON serializer.
- ✅ Block non-production with
X-Robots-Tagkeyed on the environment, not a file someone must remember to swap.
Do's and Don'ts
Do
- ✅ Emit absolute canonical, hreflang, sitemap, and
og:urlvalues on the production domain. - ✅ Allow
.xmlin your rewrite conditions and confirm sitemap selectors pass the filter. - ✅ Set
sling:redirectStatusto301on permanent redirecting vanity URLs. - ✅ Give each paginated page a self-referencing canonical and never ignore pagination parameters in
/ignoreUrlParams.
Don't
- ❌ Don't concatenate
page.getPath() + ".html"in components — it bypasses mappings and leaks/content/...URLs. - ❌ Don't block a URL in robots.txt when you want it
noindex— the crawler can't see the tag. - ❌ Don't let vanity URLs render in place without a canonical, or use them as a bulk redirect engine.
- ❌ Don't overwrite AEMaaCS's default Externalizer entries or set
AEM_EXTERNALIZER_*variables yourself. - ❌ Don't render a second canonical tag from custom head code on top of the Core Component's.
- ❌ Don't chain redirects across layers (CDN → Apache → AEM page redirect).
Wrapping up
Technical SEO on AEM is about one consistent URL flowing through every tier: Sling mappings shorten it on the way out, Dispatcher rewrites expand it on the way in, and the Externalizer makes it absolute — with the same SitemapLinkExternalizer feeding both sitemap and canonical so they agree. Add a sitemap scheduler, enable the page policy's hreflang option, and put redirects in the outermost layer that fits who maintains them. With those foundations in place, Open Graph, JSON-LD, and pagination are ordinary component work.
Continue with the Dispatcher guide for rewrite and caching depth, the Sling guide for resource resolution, the MSM, Live Copy & Translation guide for the multilingual structure hreflang depends on, and the Cloud Service guide for CDN and pipeline context. Then check your own site with the Broken Link Checker, Redirect Checker, and Hreflang Validator.
Discussion
Loading discussion…
Try a related tool
Subscribe to the Newsletter
Get the latest articles, tutorials, and tech insights delivered straight to your inbox. No spam, unsubscribe anytime.